Focusing on Post-Training
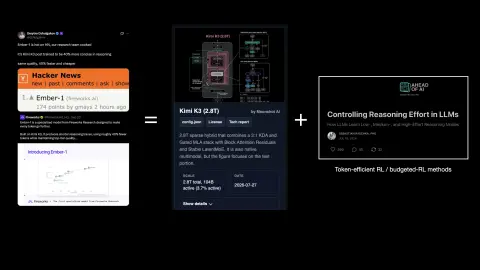
Why I'd invest in post-training existing open-weight LLMs, with Fireworks' Ember-1 as an example of more token-efficient reasoning.
Sebastian Raschka2 min read
2 stories
Why I'd invest in post-training existing open-weight LLMs, with Fireworks' Ember-1 as an example of more token-efficient reasoning.
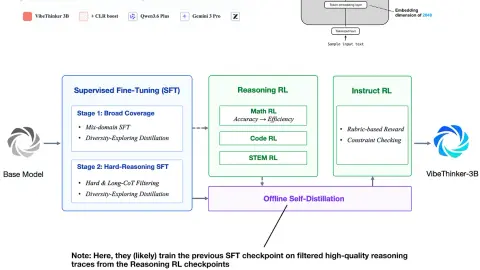
A closer look at VibeThinker-3B, a Qwen2.5-Coder-based model whose reported reasoning gains come from a detailed post-training pipeline.
Showing 2 of 2 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts