
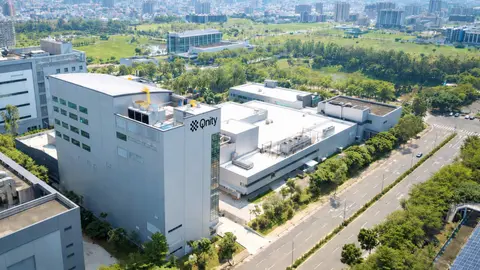
TSMC, Intel supplier Qnity bets on local production to win business
TAIPEI --The CEO of Qnity, a leading supplier of semiconductor chemicals and materials, says a "local-for-local" strategy, including sourcing more tha
Nikkei Asia Tech1 min read
22 stories
TAIPEI --The CEO of Qnity, a leading supplier of semiconductor chemicals and materials, says a "local-for-local" strategy, including sourcing more tha
Manufacturing maintains nine-month growth streak despite soaring costs and trade barriers. The post U.S. Manufacturing Activity Sustains Growth in September as Backlogs Surge appeared first on EE Times.
Upside Parts, a Massachusetts-based custom manufacturing company, released an analysis of more than 30,000 3D-printed parts produced across hundreds of customer orders, looking at how robotics companies use on-demand 3D printing. Robotics customers accounted for 82.3 percent of total part volume.
NEW YORK -- Honda Motor will push back mass production of its next-generation hybrid vehicles in North America by several months, Nikkei has learned.P
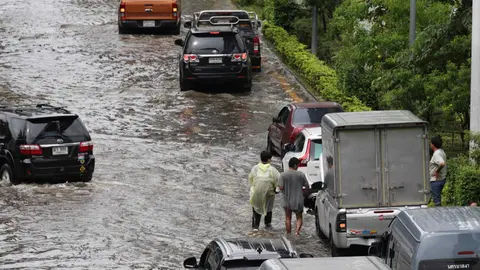
BANGKOK -- Honda Motor paused production at its Bangkok motorcycle plant Monday amid heavy rains since late last week that have caused problems for a
A long conversation costs far more than its number of turns suggests, because every request carries the system prompt and the entire history again, so total input grows with the square of the number of turns.
The Claude API costs between $1 and $10 per million input tokens and between $5 and $50 per million output tokens on Anthropic's current models.
Prompt injection hijacks your LLM via user input, retrieved docs, and tool results. Three attack surfaces, and the defenses that actually work in production.
Per-user LLM cost at 1,000 daily users in 2026: token math across chat, extraction, and RAG at two model tiers, with break-even math for solo devs.
Why LLMs hallucinate, the three error types, prompting patterns that reduce them, and the one production eval that catches failures before your users see them.
Per-session cost math for 1,000 daily LLM chat sessions at three model tiers. Why stateless APIs compound costs and when sliding-window compaction pays off.
Sliding window, summarization compaction, priority truncation: three Node.js patterns for managing context in long-running LLM conversations.
A system prompt is the hidden instruction block that shapes every LLM response. Here's how it works, what it costs, and the production pitfalls to avoid.
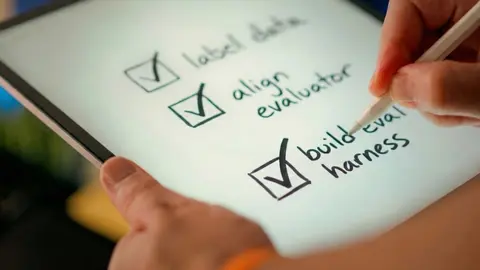
Label some data, align LLM-evaluators, and run the eval harness with each change.
Recsys & search are converging with LLMs via semantic IDs, data augmentation, and unified foundation models.
Chip Huyen and I share what we've learned, best practices, and insights at NVIDIA GTC 2025.
Deep agents aren't like simple chat applications. A single task might make 10-50+ LLM calls, take minutes, and cost $1-10+. Here's what I wish I knew from day one about running them in production.
ML systems, production & scaling, execution & collaboration, building for users, conference etiquette.
Showing 18 of 22 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts