Release v5.13.0
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training. - Release Release v5.13.0 · huggingface/transformers
195 stories
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training. - Release Release v5.13.0 · huggingface/transformers
🤗 Diffusers: State-of-the-art diffusion models for image, video, and audio generation in PyTorch. - Release Diffusers 0.39.0: New image and video pipelines, core library improvements, and more · huggingface/diffusers
Nine papers at ICML 2026 across the full stack. The research that becomes the Together platform. Find us at booth B714 in Seoul.
Go ahead and axolotl questions. Contribute to axolotl-ai-cloud/axolotl development by creating an account on GitHub.
Discover the evolution of the YOLO family of models, revolutionizing real-time object detection with faster, accurate versions from YOLOv1 onwards. The post YOLO Explained: From v1 to Present appeared first on viso.ai.
Una evaluación piloto del riesgo de despliegue no autorizado en empresas de IA de frontera. En febrero de 2026, METR inició un ejercicio piloto para evaluar riesgos de desalineación derivados de agentes de IA usados dentro de empresas desarrolladoras de IA de frontera, con la participación de…
2026 年 2 月,METR 开展了一项试点研究,对前沿 AI 公司在实验室内部使用 AI 智能体时可能出现的不对齐风险进行了评估。Anthropic、Google、Meta 和 OpenAI 参与了这项试点。报告正文分为三部分:
A pilot assessment of rogue deployment risk at frontier AI companies. Starting in February 2026, METR conducted a pilot exercise to assess misalignment risks from AI agents used inside frontier AI developers, with participation from Anthropic, Google, Meta, and OpenAI.
🤗 Diffusers: State-of-the-art diffusion models for image, video, and audio generation in PyTorch. - Release Diffusers 0.38.0: New image and audio pipelines, Core library improvements, and more · huggingface/diffusers
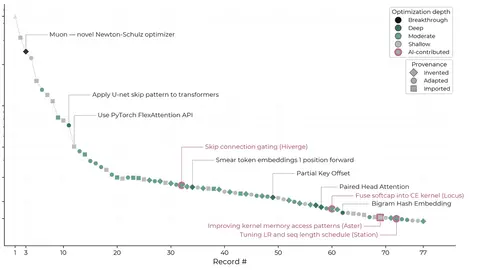
Classifying human and agent contributions to the NanoGPT speedrun, and what publicly tracked challenges can tell us about AI R&D acceleration.
The 10 most common PyTorch tensor shape RuntimeErrors explained with root causes and code fixes. Stop guessing and fix your shape mismatches.
Quick-reference formulas for every PyTorch layer's output shape. Worked examples with real numbers for Conv2d, Linear, LSTM, MaxPool2d, MultiheadAttention, and more.
Go ahead and axolotl questions. Contribute to axolotl-ai-cloud/axolotl development by creating an account on GitHub.
🤗 Diffusers: State-of-the-art diffusion models for image, video, and audio generation in PyTorch. - Release Fixes for AutoModel type hints in Modular Pipelines and Flux Klein LoRA loading · huggingface/diffusers
Go ahead and axolotl questions. Contribute to axolotl-ai-cloud/axolotl development by creating an account on GitHub.
🤗 Diffusers: State-of-the-art diffusion models for image, video, and audio generation in PyTorch. - Release Diffusers 0.37.0: Modular Diffusers, New image and video pipelines, multiple core library improvements, and more 🔥 · huggingface/diffusers
Author: Lucy Liu Note: this blog post is a cross-post of a Quansight Labs blog post.
As video diffusion models scale, sequence lengths get uncomfortably large. A practical answer is context parallelism, and within that family, Ulysses is the canonical approach. The core idea is simple: full sequence, sharded heads.
Showing 144 of 195 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts