Flash, now the Nix way: run the Flash CLI straight from GitHub
Flash now ships a first-class Nix flake. Run the CLI with nix run github:runpod/flash, get a pinned dev shell, and send GPU work to Runpod Serverless.
RunPod10 min read
188 stories
Flash now ships a first-class Nix flake. Run the CLI with nix run github:runpod/flash, get a pinned dev shell, and send GPU work to Runpod Serverless.
Deep learning is not a single library command that turns data into intelligence. A useful model depends on the problem definition, data quality, mathematical assumptions, architecture, training loop, evaluation, deployment and monitoring.
Optimize multi-node GPU cluster performance and cost-efficiency by aligning parallelism strategies, network fabric selection, and performance benchmarking.
https://preview.redd.it/m5e9anluo8vh1.png?width=1080&format=png&auto=webp&s=4c80687e6fe40036843a97ed8975ce46eaab0662 I am excited to share a project I have been working on during the past few years during my free time.
TL;DR The PyTorch-based software stack for IBM’s Spyre accelerator recently moved its torch.compile backend from sendnn, a separate compilation stack built entirely from scratch, to backend=inductor, an open-source backend built...
Two things are true about Python: It’s the most popular programming language in the world, and it’s the most common companion language for Go developers. How do we know that? From the Developer Ecosystem 2026 survey by JetBrains.
Medical image quality is essential for reliable clinical diagnosis and downstream artificial intelligence analysis, yet routine images are often degraded by noise, motion artefacts, low contrast, low-dose acquisition or modality-specific artefacts.
Article URL: https://www.intel.com/content/www/us/en/products/details/discrete-gpus/data-center-gpu/d-series.html Comments URL: https://news.ycombinator.com/item?id=50063365 Points: 48 # Comments: 17
You can teach an open-weight LLM to text like a specific persona: their slang, their reply length, their humor, even how they write in a roleplay scene, creative writing exercise, or chatbot customer interactions.
We sponsored TreeHacks 2026 at Stanford, where teams built on Runpod across 36 hours, shipping projects ranging from GPU-accelerated cancer drug discovery.
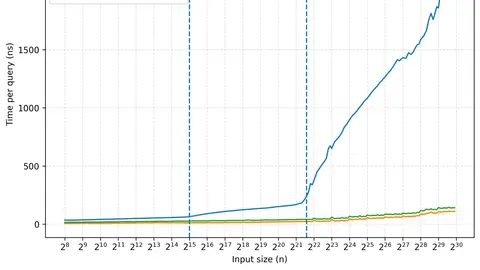
We explore how to speed up binary search by batching independent searches with NumPy's vectorized operations. We then reformulate the algorithm so all searches progress together with only $O(1)$ additional memory, port it to C++, and achieve up to a 25× speedup over NumPy 2.4's implementation.
Want a custom spin on Stable Diffusion? This post shows you how to create and launch your own Vlad Diffusion template inside Runpod.
Learn how to train, deploy, and scale AI/ML models using Runpod Serverless. This guide covers real-world examples, deployment best practices, and how.
Runpod and Defined.ai launch a pilot program to provide startups with access to high-quality training data and compute, enabling sector-specific.
Runpod’s new REST API lets you manage GPU workloads programmatically, launch, scale, and monitor pods without ever touching the dashboard.
Article URL: https://nishtahir.com/build-your-own-decision-model/ Comments URL: https://news.ycombinator.com/item?id=50037949 Points: 266 # Comments: 61
New work from engineers at the Johns Hopkins Applied Physics Laboratory (APL) in Laurel, Maryland, shows a technology normally used to spray protective coatings onto industrial parts could help address a costly problem in hypersonics: deciding which materials deserve time in the nation's scarce…
EmbeddingGemma 2 launched on October 6, 2026 under Apache 2.0. It is a sub-1B model built on Gemma 4 that maps text, code, images, video and audio into one 768-dimensional space. This article covers the architecture, the benchmarks, and runnable scripts to provide measured results.
Showing 18 of 188 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts