v0.13.1
Go ahead and axolotl questions. Contribute to axolotl-ai-cloud/axolotl development by creating an account on GitHub.
Axolotl4 min read
195 stories
Go ahead and axolotl questions. Contribute to axolotl-ai-cloud/axolotl development by creating an account on GitHub.
🤗 Diffusers: State-of-the-art diffusion models for image, video, and audio generation in PyTorch. - Release Diffusers 0.36.0: Pipelines galore, new caching method, training scripts, and more 🎄 · huggingface/diffusers
Go ahead and axolotl questions. Contribute to axolotl-ai-cloud/axolotl development by creating an account on GitHub.
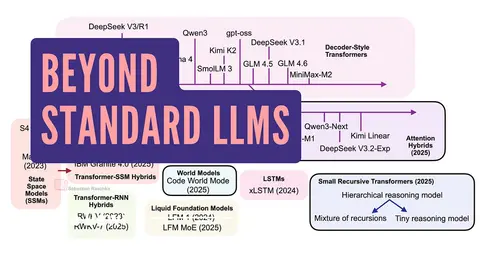
Linear Attention Hybrids, Text Diffusion, Code World Models, and Small Recursive Transformers
🤗 Diffusers: State-of-the-art diffusion models for image, video, and audio generation in PyTorch. - Release 🐞 fixes for `transformers` models, imports, · huggingface/diffusers
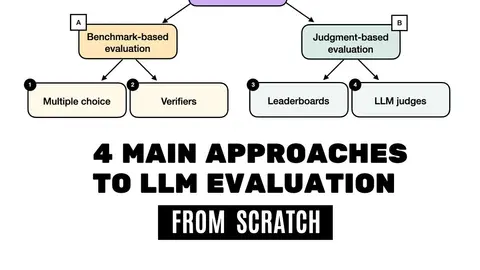
Multiple-Choice Benchmarks, Verifiers, Leaderboards, and LLM Judges with Code Examples
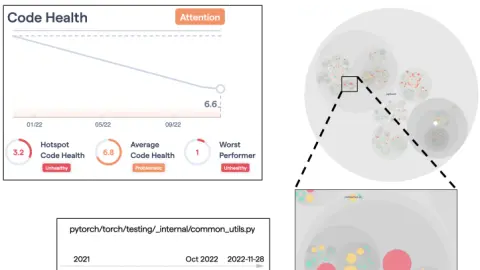
Technical debt slows teams down. Learn how explicit requirements, ISO 5055 standards, and CodeScene’s Code Health can guide sustainable code quality.
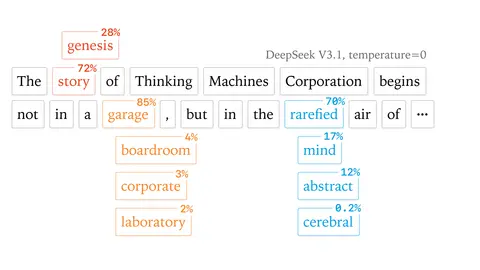
Reproducibility is a bedrock of scientific progress. However, it’s remarkably difficult to get reproducible results out of large language models.
Cache your compiled models for faster boot and inference times
AI isn’t a specialty anymore, it’s the foundation of modern software. In this guide, Ali breaks down the best programming languages for AI in 2025 and how your choice can make or break speed, workflow, and realworld result
Frontier model training has pushed GPUs and AI systems to their absolute limits, making cost, efficiency, power, performance per TCO, and reliability central to the discussion on effective training. The Hopper vs Blackwell comparisons are not as simple as Nvidia would have you believe.
🤗 Diffusers: State-of-the-art diffusion models for image, video, and audio generation in PyTorch. - Release v0.35.1 for improvements in Qwen-Image Edit · huggingface/diffusers
🤗 Diffusers: State-of-the-art diffusion models for image, video, and audio generation in PyTorch. - Release Diffusers 0.35.0: Qwen Image pipelines, Flux Kontext, Wan 2.2, and more · huggingface/diffusers
We're excited to announce our collaboration with NVIDIA to launch the Stable Diffusion 3.5 NIM microservice, enabling significant performance improvements and streamlined enterprise deployment for our leading image generation models.
🤗 Diffusers: State-of-the-art diffusion models for image, video, and audio generation in PyTorch. - Release Diffusers 0.34.0: New Image and Video Models, Better torch.compile Support, and more · huggingface/diffusers
We have some very fast AI-generated kernels in pure CUDA-C without using libraries and DSLs such as CUTLASS and Triton. They are performing close to or in some cases even beating the standard expert-optimized production kernels shipped in PyTorch. Some of our highlighted results:
We’ve collaborated with AMD to deliver select ONNX-optimized versions of the Stable Diffusion model family, engineered to run faster and more efficiently on AMD Radeon™ GPUs and Ryzen™ AI APUs.
In artificial intelligence, multimodal agents are becoming increasingly popular for their ability to understand and integrate multiple types of input, such as text and images.
Showing 162 of 195 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts