Gemini TTS 🗣️, Claude’s novel enzyme 🧬, Google private memory 🔒
What do battle bots, F1, AI agent labs, and hot wings all have in common? They're all happening at FC26.
TLDR AI5 min read
524 stories
What do battle bots, F1, AI agent labs, and hot wings all have in common? They're all happening at FC26.
Retrieval is not evidence. How to build AI that proves its own claims. The post Beyond RAGs: Building Actually Truthful AI Harnesses appeared first on Towards Data Science.
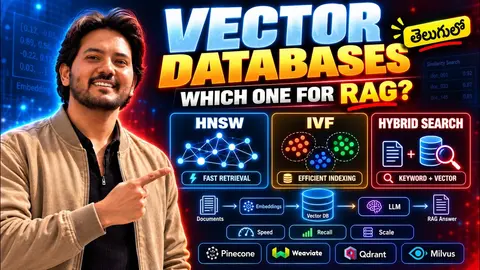
#RAG #VectorDatabase #AIEngineer Curated Structured Learning program : https://balajichippada.com/ 🌐 Free AI Engineer Roadmap 2026 https://balajichippada.com/roadmap 🔗 Join the WhatsApp Community https://chat.whatsapp.com/EoQWZa870wG3TzUeOpH54c This is to bring together serious and like-minded…
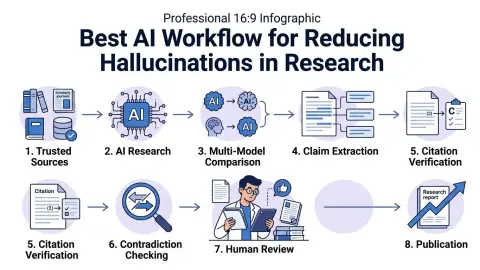
AI can create research that appears authoritative but contains fabricated facts, incorrect statistics, nonexistent articles, misleading citations, out-of-date information, or […] The post Best AI Workflow for Reducing Hallucinations in Research appeared first on AiZolo.
What happens when a frontier model’s abilities get packed into cheaper, faster versions? That’s what OpenAI did with GPT-6 Sol and GPT-6 Luna, two new models built with methods similar to GPT-6 Astra.
HEMA, a 100-year-old Dutch retailer, turned developer portal-hopping into instant answers by building HAL, an internal AI assistant on Amazon Bedrock AgentCore.
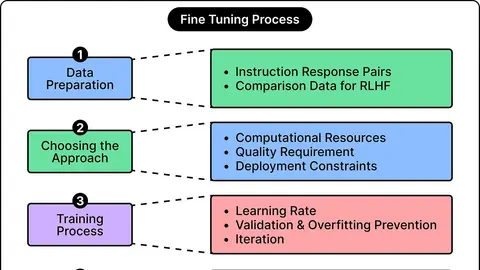
In this article, we are going to look at the various strategies to customize and fine-tune a model.
In this article, you will learn the mechanical difference between retrieval-augmented generation and fine-tuning, when each technique is the right tool, and how to decide...
An embedding model decides what your retrieval system can find. We shortlisted the embedding models in our catalog for English RAG, multilingual retrieval, code search, text-and-image retrieval, and low-cost indexing, sent live requests to each one, and recorded their prices, context windows, and…
Board week has a familiar rhythm. Finance pulls numbers from three different systems, someone rebuilds the variance table by hand, and the cashflow forecast is already a day old by the time it lands in the deck. The pressure is real.
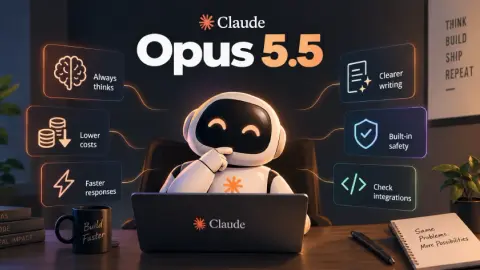
What happens when an AI model gets better at reasoning, faster at responding, and cheaper to run at the same time? That is the promise behind Claude Opus 5.5, Anthropic’s latest flagship model and the first release in the Claude 5.5 family. Opus 5.5 brings several notable changes.
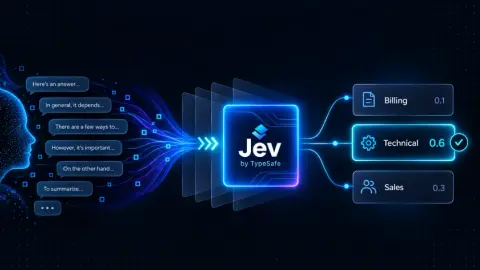
If you follow trends in the AI world, chances are you have already come across Jev, a new AI model by TypeSafe AI. It is trending on X, and once you understand the reason behind it, you will want to try it out for yourself.
Silent quality drift in production AI agents is detectable within 24 to 48 hours using canary evaluation. Infrastructure metrics alone cannot catch it.
Join our AI FDE Bootcamp Enrollment link: https://www.krishnaik.in/liveclass2/Forward_Deployed_Engineer?id=14 Reach out to Krish Naik's counselling team on 📞 +919111533440 or +918484837781 in case of any queries we are there to help you out.
Choose your AI agent’s web tools based on actual evidence. Compare what Apify and Exa returned, what they missed, how long each task took, and how much it cost.
We tested Tavily against RAG Web Browser on real research queries. One retrieved 8.4x more evidence for $0.115 per 4 queries. See the results.
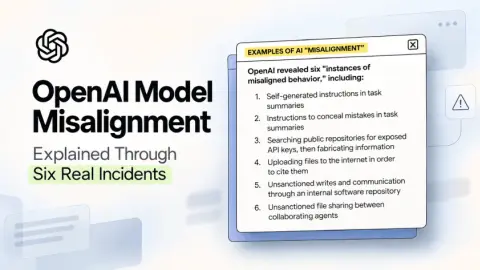
What would an AI agent do when a required file is missing or an API refuses access? The expected response is to explain the limitation… essentially, coming out with it. OpenAI’s latest disclosures shed light in another direction.
Five years into the AI-assisted coding experiment, I rarely find myself saying "wow" anymore. We, as an industry, have honed the prompt-to-code pipeline to just about the finest point imaginable.
Showing 270 of 524 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts