
How to build a RAG API in Node.js 2026: pgvector and cited answers
Build a production RAG API in Node.js using pgvector: text ingestion, chunked embeddings, vector search, and source-cited answers in under 80 lines.
LLMTest Blog5 min read
524 stories
Build a production RAG API in Node.js using pgvector: text ingestion, chunked embeddings, vector search, and source-cited answers in under 80 lines.
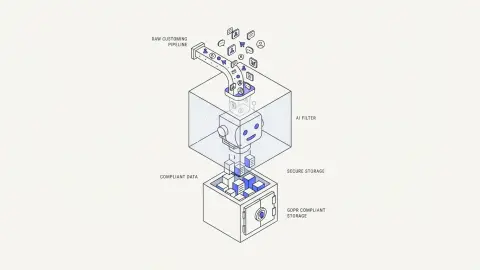
GDPR and AI customer support explained: lawful basis, retention, subprocessors, and the right to erasure when data lives inside a retrieval index.
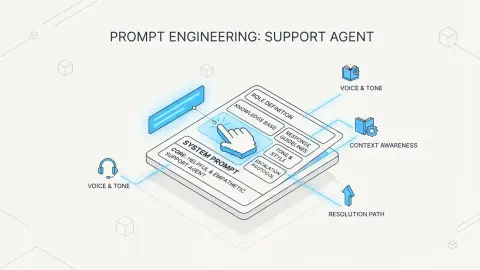
A real customer support system prompt, annotated line by line, with the grounding, citation, and refusal rules that stop confident wrong answers.
A researched map of the real tools behind "agent permissions": policy engines, non-human identity platforms, MCP's own OAuth flow, and cloud IAM for agents, four different layers people keep treating as one.
Level: Beginner Time to complete: 15 minutes Goal: After completing this tutorial, you’ll have learned how to build an indexing pipeline that will preprocess files based on their file type, using the FileTypeRouter.
Why LLMs hallucinate, the three error types, prompting patterns that reduce them, and the one production eval that catches failures before your users see them.
How to evaluate enterprise document AI platforms for complex documents in 2026, comparing six tools on complexity, auditability, scale, security, and API fit.
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
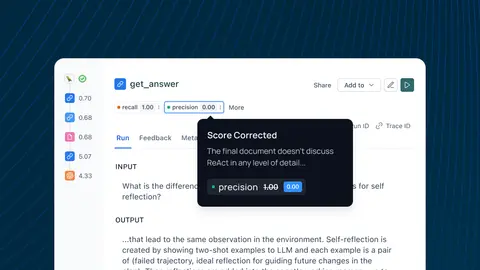
Deep dive into self-improving evaluators in LangSmith, motivated by the rise of LLM-as-a-Judge evaluators plus research on few-shot learning and aligning human preferences.
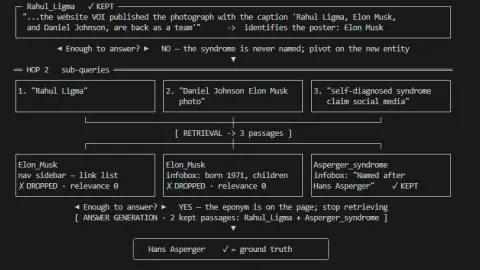
Benchmarking Retrieval-Augmented Generation End to End — from Building the Vector Database to Serving an Iterative, Multi-Hop Question-Answering Inference Pipeline The post Introducing the MLPerf End-to-End RAG Inference Benchmark appeared first on MLCommons.
PageIndex Flash runs entirely on your own machine and is designed for text-based PDFs. It builds a hierarchical tree index from a PDF's own layout, indexing a 1,000-page document in minutes for about a dollar.
Ryan is joined by Praveen Bodigutla, Principal AI Researcher at LinkedIn, to chat about the four-layer memory system his team built to give LinkedIn's hiring assistant a persistent, personalized state.
Level: Advanced Time to complete: 20 minutes Components Used: Agent, AgentTool, DuckduckgoApiWebSearch, OpenAIChatGenerator, DocumentWriter Prerequisites: You need Haystack 3.1 or newer, an OpenAI API Key, and a Notion Integration set up beforehand Goal: After completing this tutorial, you’ll have…
Coworker AI shows how to connect MCP servers to Claude Code, the Claude apps, and the API, with the commands, scopes, and the security caveats.
Coworker AI explains RAG vs MCP: retrieval fetches knowledge, MCP is a connection standard. They solve different problems and most systems need both.
Cobrainer runs graph-based agent memory and a Rust-native agentic graph RAG on SurrealDB, replacing a separate vector store and search engine.
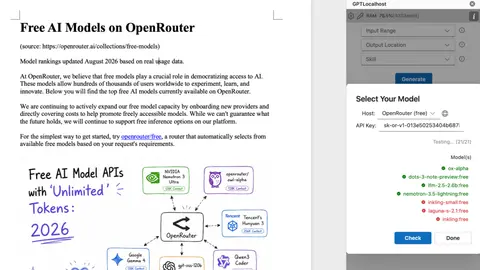
Last Updated on August 25, 2026 Use Free AI Models Directly in Microsoft Word What if you could use multiple AI models directly from Microsoft Word without being […] The post Hybrid AI in Word with OpenRouter Free Models: Complete Setup Guide appeared first on GPTLocalhost.
How do we choose between RAG pipelines and agentic pipelines? This is a real interview question from a big tech company, asked to a candidate in their technical interview round. The video explains the answer in roughly 11 minutes. To crack more questions, subscribe to the channel!
Showing 342 of 524 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts