Building a RAG Pipeline with LLM Embeddings and Scikit-learn
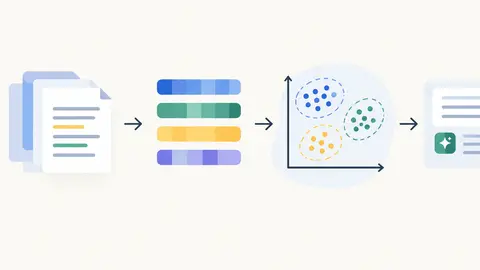
In this article, you will learn how to build a lightweight, end-to-end RAG pipeline using scikit-learn for vector retrieval and open-source models for embeddings and...
494 stories
In this article, you will learn how to build a lightweight, end-to-end RAG pipeline using scikit-learn for vector retrieval and open-source models for embeddings and...
Four architectures, one ladder. What each rung adds, what it really costs, how it fails, and how to pick the lowest rung that solves your problem well.
In June 2026, Ahrefs pulled server logs from 137,000 domains and examined which ones were actually getting their llms.txt files read by AI crawlers. The result was stark: 97% of llms.txt files received zero recorded visits from AI bots.
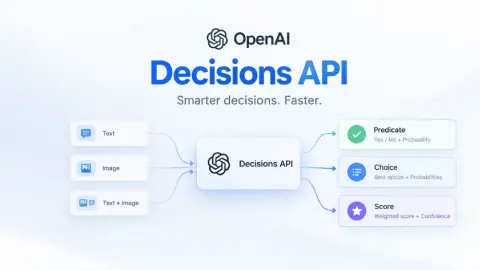
Imagine building an AI agent that has to decide whether a customer complaint needs human intervention, which department should handle a query, or whether a submitted delivery photo is valid. Getting these decisions right matters.
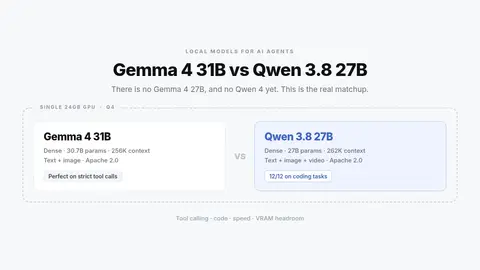
Searching for Gemma 4 27B or Qwen 4 27B? Neither exists yet. The real matchup is Gemma 4 31B vs Qwen 3.8 27B: tool calling, code, speed and VRAM on a 24GB card.
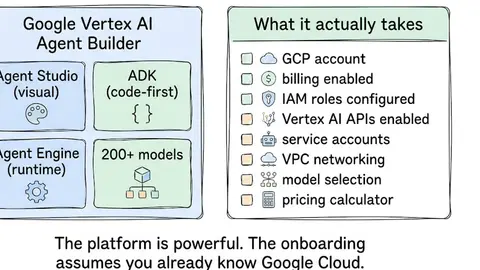
Vertex AI Agent Builder pricing checked Oct 13, 2026: Gemini 3.8 Flash at $0.75/$3.75, Claude and open models, every agent meter, free tier, 3 worked bills.
A local embedding model turns your text into vectors on hardware you control, so no document or query leaves your machine to get embedded.
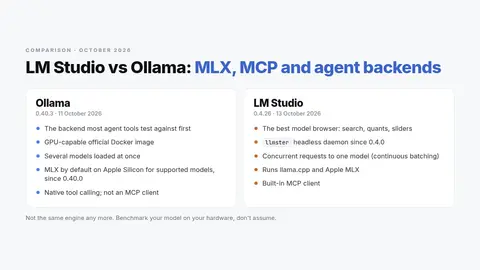
LM Studio vs Ollama, October 2026: Ollama now runs MLX on Macs and both run headless. Where each wins on GPU Docker, concurrency, MCP and agent backends.
Article URL: https://www.intel.com/content/www/us/en/products/details/discrete-gpus/data-center-gpu/d-series.html Comments URL: https://news.ycombinator.com/item?id=50063365 Points: 48 # Comments: 17
AI search is changing how agencies measure success. Learn how to guide clients through the shift from rankings to AI-generated answers, balance SEO and GEO, and prove value beyond clicks and traffic.
Building RAG from Scratch: No Frameworks Needed Understand Retrieval-Augmented Generation by building it yourself — pure Python, zero dependencies. Introduction LangChain, LlamaIndex, Haystack — great tools, but they hide how RAG actually works.
Learn how to deploy one large language model across two GPU nodes on Amazon EKS using the multi-node Ray LLM Deep Learning Containers, with separate prefill and decode nodes behind one OpenAI-compatible endpoint.
A 90-day architectural blueprint for scaling from prototype to mission-critical availability.
Explore 10 Hugging Face models used across text, vision, audio, and retrieval in 2026.
Comparing Apify's RAG Web Browser with Jina AI Search: one query, same LLM briefing task. Which one retrieved more usable evidence, and what did it cost?
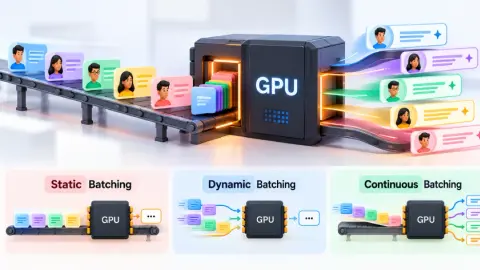
Imagine four people booking a ride to the same destination. If each person takes a separate taxi, four vehicles make the same trip. But if they travel together in a bus, everyone reaches the destination in a single trip. The bus carries more people at once and makes better use of the resources.
We present SmartSalesBench, the first multi-turn conversational benchmark explicitly designed to evaluate large language model (LLM) sales agents against psychologically grounded, resistant buyer personas.
On-behalf-of tokens (Databricks), live ACL re-checks (AWS), and parent-level fine-grained authorization: how each keeps an AI assistant from showing users data they can't access, and when to use which.
Showing 36 of 494 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts