
Multi-Turn LLM Evaluation in 2026: What You Need to Know
In this article, I'll break down multi-turn LLM evaluation — how it differs from single-turn, what metrics actually matter, and how to implement it.
Confident AI (DeepEval)14 min read
525 stories
In this article, I'll break down multi-turn LLM evaluation — how it differs from single-turn, what metrics actually matter, and how to implement it.
Kiln has added agent skills support! Here's what skills are, why progressive disclosure works, and how to use them in your agents.
Sim v0.6 introduces Mothership—a central intelligence layer for orchestrating your AI agents—alongside Tables, Files, Knowledge Base Connectors, and Scheduled Tasks.
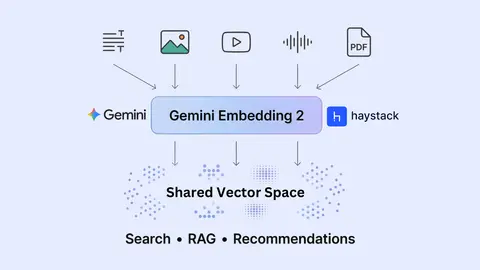
Embeddings are the backbone of modern AI applications, from semantic search and recommendation systems to Retrieval-Augmented Generation (RAG). However, most embedding models operate in a single modality, typically focusing only on textual data.
How to Increase Employee Productivity? When a startup grows and brings in talented people, it should move faster. However, the reality is often the opposite. Yet with more people and stronger skills on the team, decisions slow down and communication starts to break.
OpenAI released GPT-5.4 with a Pro variant for extended reasoning. We tested both on our LLM-for-RAG leaderboard across three workloads.
LibreChat has quickly become a favorite for developers and technical teams who want a self‑hosted, open‑source chat UI that can sit in front of multiple LLMs. It gives you flexibility and control without per‑seat SaaS pricing.
We evaluated Claude Sonnet 4.6 in a RAG setup across factual retrieval, synthesis, and scientific tasks compared to frontier models.
Use this AI persona deployment checklist to prevent shadow AI, enforce access rules, validate accuracy, and roll out reliable AI personas.
We tested Gemini 3 inside an actual retrieval setup and compared it directly with GPT-5.1 across five areas that matter for RAG.
We evaluated Claude Opus 4.6 in a RAG setup across factual retrieval, synthesis, and scientific tasks versus 11 frontier models.
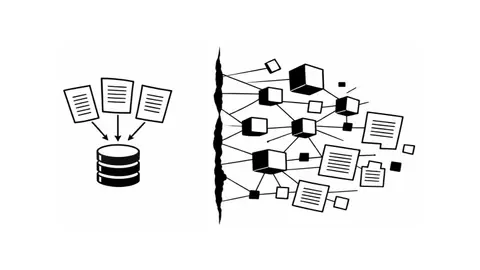
We argue that context blindness — the inability of vector-based retrieval to condition on full conversational and reasoning context — is a fundamental limitation of vector RAG, and outline a paradigm shift from semantic similarity to context-dependent relevance classification.
VentureBeat covers PageIndex, the vectorless, reasoning-based RAG framework that uses tree search over document structure to reach 98.7% accuracy on FinanceBench, where vector-based retrieval typically fails.
This new release brings a state of the art Copilot, seamless MCP server and tool deployment, 100+ integrations with 300+ tools, comprehensive execution logs, and realtime collaboration—built for teams shipping AI agents in production.
Tabstack is the web execution layer for AI agents. Automate workflows and turn web content into clean data with a developer API backed by Mozilla.
We evaluated Gemini 3 Flash in a RAG setup to understand where it excels and where it falls short—focusing on factual retrieval and grounding.
Indepth 2025 review of the best AI memory systems for developers. Compare architectures, features, use cases, and performance
How PageIndex’s vectorless, reasoning-based RAG overcomes the challenges of traditional vector RAG in long, complex technical manuals.
Showing 450 of 525 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts