
HELM Long Context
We introduce the HELM Long Context leaderboard for transparent, comparable and reproducible evaluations of long context capabilities of recent models.
Alpaca Blog18 min read
527 stories
We introduce the HELM Long Context leaderboard for transparent, comparable and reproducible evaluations of long context capabilities of recent models.
Introducing our biggest release ever! Build state-of-the-art RAG systems in minutes, with drag-and-drop!
PageIndex is a vectorless, reasoning-based retrieval framework that simulates how human experts extract knowledge from complex documents. Instead of relying on vector similarity search, it builds a tree-structured index from documents and enables LLMs to perform agentic reasoning over that…
Understanding how vector databases and LLMs work together, why they complement each other.
If you only track MRR, you'll miss the cliff. Here's the margin scorecard operators actually use to stay profitable.
The evolution of AI agents, framework choices, and production challenges. Modern agent development with VoltAgent and VoltOps.
The same bet behind both PageIndex and Claude Code: skip the vector DB and let the LLM itself drive retrieval. We explore the rise of agentic retrieval over vector indexing and PageIndex's agentic, vectorless RAG framework.
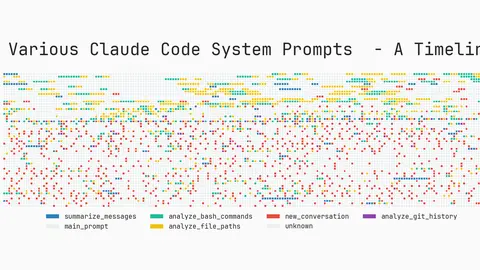
Claude Code is the most delightful AI agent/workflow I have used so far. Not only does it make targeted edits or vibe coding throwaway tools less annoying, ...
Cue is one of the latest and most complex AI development tool features developed by TRAE. We explored the technical challenges, achievements as well as future plans for TRAE Cue.
Upload documents into datasets with built-in OCR, write deterministic function evals for objective checks, and run evaluations async from the SDK.
Every LLM application builder faces a fundamental tradeoff: large models deliver superior performance at higher costs, while small models are affordable but often underperform. This choice becomes critical when scaling to production workloads where inference costs can quickly explode.
Voice has emerged as a widely adopted modality in applied AI. From call centers to scheduling assistants, voice agents are entering more production use cases across various industries than ever before. Despite how natural it feels to speak, building low-latency, conversational voice agents remains…
Evaluation metrics, how to build eval datasets, eval methodology, and a review of several benchmarks.
Welcome to this step-by-step tutorial where we’ll build a simple Retrieval-Augmented Generation (RAG) pipeline using Haystack and OPEA. We’ll fetch the newest Hacker News posts, feed them to a lightweight LLM endpoint (OPEAGenerator), and generate concise one-sentence summaries (based on this…
RAG evaluation metrics — answer relevancy, faithfulness, and contextual relevancy — measure retrieval and generation quality, with working DeepEval code examples.
What I learned performing work with RAG and Fine-tuning. A calm tutorial to choose the right method, full of real experiences for newbies.
Most teams are curious about fine-tuning and how it might help their AI products, but they don't know what to expect from the process, how to measure success, or where to start.
Handcrafted tricks break at scale. The future of code comprehension lies in holistic, learning-based systems.
Showing 486 of 527 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts