Focusing on Post-Training
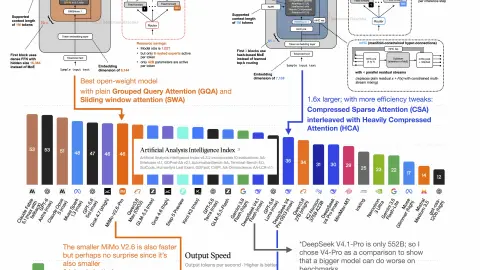
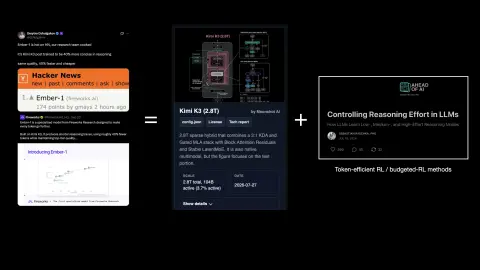
Why I'd invest in post-training existing open-weight LLMs, with Fireworks' Ember-1 as an example of more token-efficient reasoning.
Sebastian Raschka2 min read
25 stories
Why I'd invest in post-training existing open-weight LLMs, with Fireworks' Ember-1 as an example of more token-efficient reasoning.
Notes on MiMo-V2.6 Pro's GQA and sliding-window attention, agent training tasks, reward signals, and large RL batches.
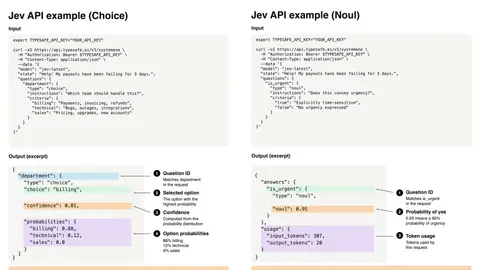
A short note on Jev's generalization, possible encoder-style architecture and training, and Choice and Noul API examples.
My take on AI model pacing as a framework for release checks and the competitive pressure around model releases.
A 90-minute LinkedIn Learning course on how reasoning models relate to conventional LLMs and how they are developed.
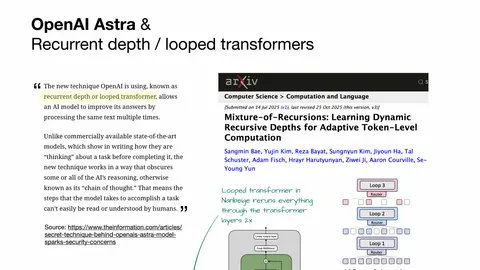
A short note on OpenAI Astra, recurrent depth, looped transformers, Nanbeige 4.2, and the Mixture-of-Recursions paper.
A short video on how conventional LLMs relate to reasoning models and agents, along with Python and PyTorch setup using uv.
Two free live book club Q&A sessions on September 3 about Build a Reasoning Model From Scratch and related reader questions.
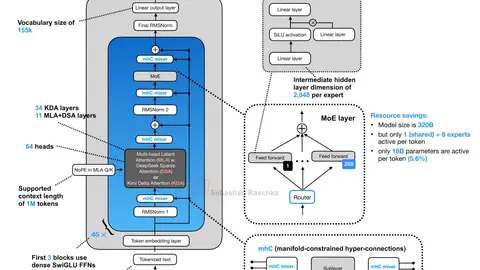
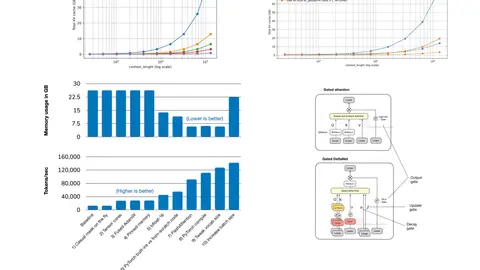
Architecture note on GLM-5.3-Flash, formerly Ox Alpha, covering its KDA and MLA/DSA hybrid attention, sparse MoE backbone, and four-stream mHC residual path.
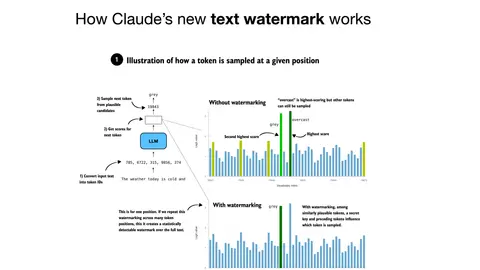
Short illustration of how Claude's text watermarking is supposed to work based on Anthropic's released materials.
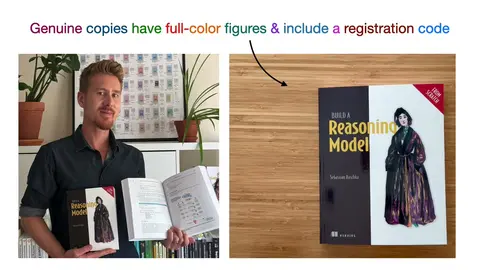
Short note on the Amazon availability of Build a Reasoning Model From Scratch and a warning about counterfeit black-and-white copies sold through Amazon India.
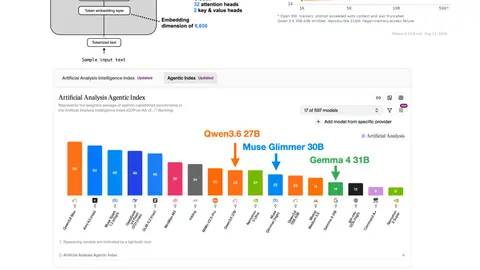
Short architecture note on Meta Muse Glimmer 30B, including gated local and global GQA, KV-cache efficiency, and release-time benchmark comparisons.
Short note celebrating the LLMs-from-scratch repository passing 100,000 GitHub stars and summarizing its learning materials.
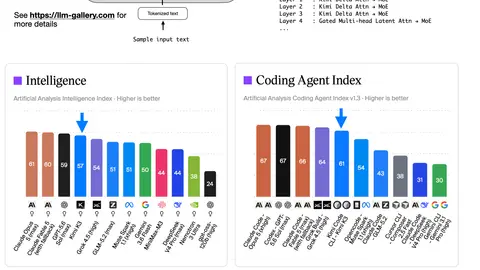
Short architecture note on Kimi K3, including LatentMoE, Kimi Delta Attention, Attention Residuals, NoPE, multimodality, and inference-efficiency choices.
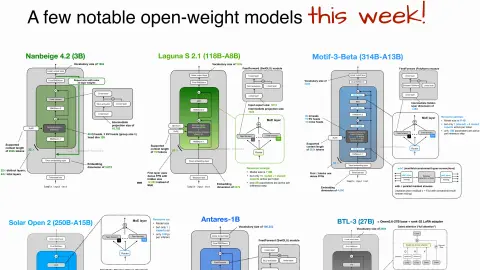
Short note on the architectures of six new open-weight models, including Nanbeige 4.2, Laguna S 2.1, Motif-3-Beta, Solar Open 2, Antares 1B, and BTL-3.
Short correction note for the random seed in Listing 6.5 on page 198 of Build a Reasoning Model From Scratch.
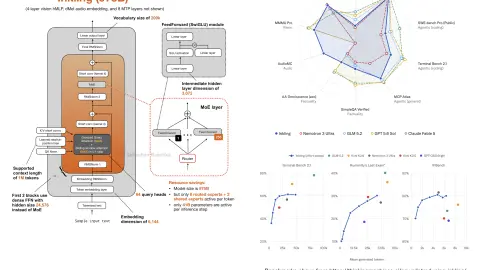
Architecture and benchmark notes on Thinking Machines Lab's 975B Inkling MoE, including short convolutions, relative-position bias, training, and effort control.
Short note celebrating Ahead of AI reaching 200,000 subscribers.
Showing 18 of 25 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts