The fastest way to serve DeepSeek V4 Flash
Historical measurements published August 2, 2026 for DeepSeek V4 Flash 0731 on four B200 GPUs. As of September 21, 2026, no current measured optimization package is published for it.
RunInfra Blog8 min read
4 stories
Historical measurements published August 2, 2026 for DeepSeek V4 Flash 0731 on four B200 GPUs. As of September 21, 2026, no current measured optimization package is published for it.
Nine cents and $290.12 are both prices for one million output tokens. The gap is driven by accelerator, provider, concurrency, utilization, and reasoning token volume.
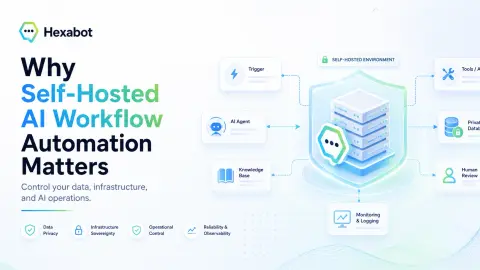
Learn why self-hosted AI automation matters for data control, compliance, customization, security, and building reliable AI agents in production.
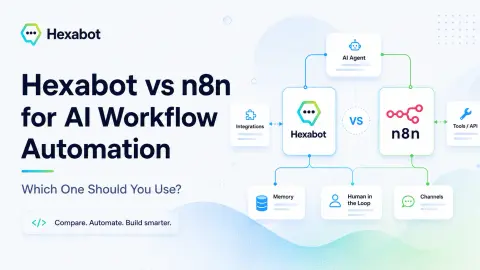
Compare Hexabot and n8n for AI automation, agentic workflows, chatbots, integrations, self-hosting, memory, extensibility, and production use cases.
Showing 4 of 4 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts