
Open SWE: An Open-Source Framework for Internal Coding Agents
Built on Deep Agents and LangGraph, Open SWE provides the core architectural components for internal coding agents.
LangChain Blog9 min read
12 stories
Built on Deep Agents and LangGraph, Open SWE provides the core architectural components for internal coding agents.
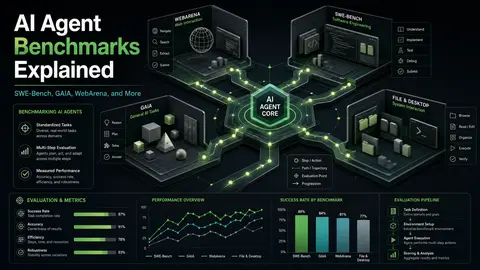
In this article, you will learn what the major AI agent benchmarks measure, how they differ from traditional model benchmarks, and how to use them...
Static coding benchmarks are fixed at release. Over time their tasks leak into training data, and stronger agents eventually saturate them. We argue that a benchmark should instead aim to be self-scaling: its tasks and oracles are created at evaluation time, so no content exists in advance to leak,…
Reinforcement learning with verifiable rewards (RLVR) provides reliable supervision for software engineering agents through executable tests, but binary rewards fail to distinguish trajectories with substantially different debugging quality.
Lenovo's in-house TianxiCode coding-agent framework, running DeepSeek-V4.1-Flash, resolved 71% of issues on the SWE-bench-Live Lite board and passed official verification.
We've been building a benchmark out of real concurrency bugs (race conditions, deadlocks, cancellation issues) taken from merged PRs in about 100 Python projects.
The most ambitious companies are training specialized models to outperform the frontier on their domain.
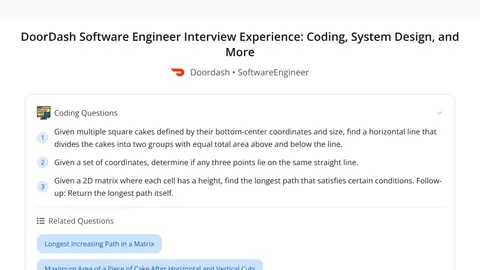
High-Score DoorDash SWE Interview Experience (Bugfree Users) Posted by Bugfree users — a concise, practical playbook from a high-scoring DoorDash Software Engineer interview. This post summarizes the interview flow, highlights the most interesting p...
High-Score DoorDash SWE Interview Experience (Bugfree Users) Posted by Bugfree users — a compact, high-yield playbook summarizing a successful DoorDash Software Engineer interview experience. This write-up covers the interview flow, the key problems...
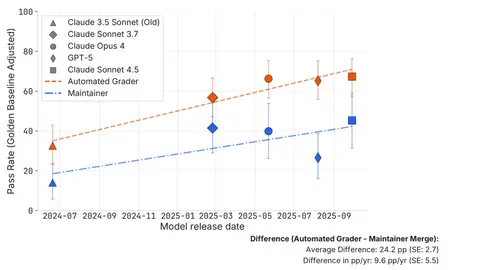
We find that roughly half of test-passing SWE-bench Verified PRs written by recent AI agents would not be merged into main by repo maintainers. A naive interpretation of benchmark scores may lead one to overestimate how useful agents are without more elicitation or human feedback.
Trae Agent reached #1 on SWE-bench Verified, with Claude 4 — and it’s open-sourced.
Trae achieves 71.0% accuracy on SWE-bench Verified with Claude 3.7,, pushing the boundaries of automated issue resolving., Not just fast. Not just big. But deeply aligned with the nature of engineering.
Showing 12 of 12 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts