Know a great AI tool or AI news source? Submit it to AiByts

Text Generation Inference

7 stories

Stories

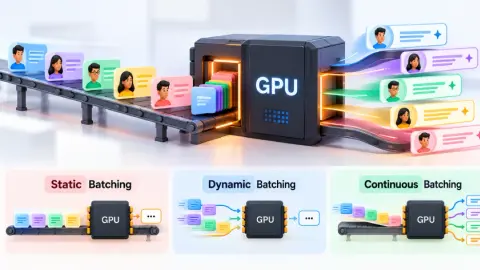
  • LLM Batching Explained: Static vs Dynamic vs Continuous Batching

    Imagine four people booking a ride to the same destination. If each person takes a separate taxi, four vehicles make the same trip. But if they travel together in a bus, everyone reaches the destination in a single trip. The bus carries more people at once and makes better use of the resources.

    Analytics Vidhya12 min read
  • Introduction to vLLM and PagedAttention

    Learn how vLLM achieves higher throughput than Hugging Face Transformers by using PagedAttention to eliminate memory waste, boost inference.

    RunPod12 min read
  • Run Llama 3.1 with vLLM on Runpod Serverless

    Discover how to deploy Meta's Llama 3.1 using Runpod's new vLLM worker. This guide walks you through model setup, performance benefits, and step-by-step.

    RunPod7 min read
  • RAG with Llama 3.1

    Simple RAG example on the Oscars using Llama 3.1 open models and the Haystack LLM framework. Installation ! pip install transformers-haystack sentence-transformers-haystack bitsandbytes Authorization you need an Hugging Face account you need to accept Meta conditions here:…

    Haystack by deepset7 min read
  • Summarize Hacker News Posts with Haystack & OPEA

    Welcome to this step-by-step tutorial where we’ll build a simple Retrieval-Augmented Generation (RAG) pipeline using Haystack and OPEA. We’ll fetch the newest Hacker News posts, feed them to a lightweight LLM endpoint (OPEAGenerator), and generate concise one-sentence summaries (based on this…

    Haystack Blog4 min read

Showing 7 of 7 stories

You're all caught up.

AiByts Weekly Brief

Get the top AI news and tools straight to your inbox every week.

Weekly · AI news

Join 15,000+ AI enthusiasts