
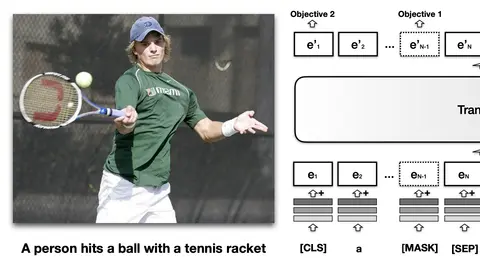
Generalized Visual Language Models
Processing images to generate text, such as image captioning and visual question-answering, has been studied for years. Traditionally such systems rely on an object detection network as a vision encoder to capture visual features and then produce text via a text decoder.
Lil'Log (Lilian Weng)21 min read