
Inference Engines explained in 10min..
Try Zapier: https://bit.ly/4yVvOtV Zapier helps you build custom automation and we're looking at how Zapier CLI can help me build news scanner app that keeps me up to date with AI.
Caleb Writes Code
261 stories
Try Zapier: https://bit.ly/4yVvOtV Zapier helps you build custom automation and we're looking at how Zapier CLI can help me build news scanner app that keeps me up to date with AI.
Vision-language models have made it possible to build visual AI agents that understand video at production scale. The harder problem is turning that capability...
Today's haul: 16 tools · 14 resources · 20 reads · 20 numbers · 35 things that happened. Every tool, resource and read below has a working link. No link, no listing.
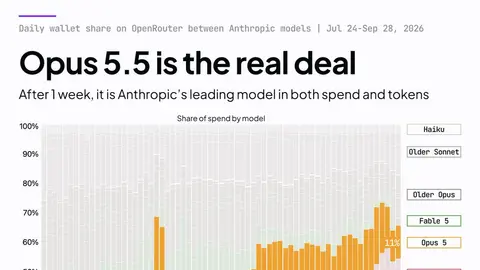
Checking in on Opus 5.5 ~1 week after launch. It's the #1 model in share of spend and share of tokens among Anthropic models on OpenRouter Switching from Opus 5 has been particularly rapid
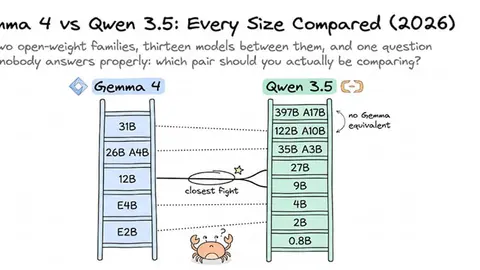
Gemma 4 vs Qwen 3.5 at every size, 0.8B to 397B, plus where Qwen 3.6 and 3.8 27B fit. Benchmarks, VRAM needs, and the right pairing for your hardware.
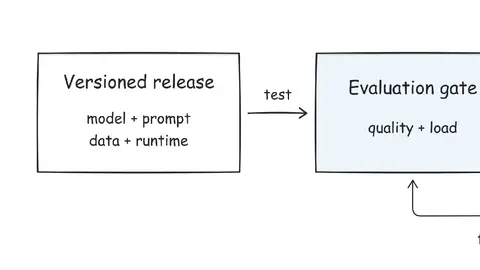
An MLOps workflow for evaluating deploying and rolling back AI applications
Deploy a text-to-speech model on Amazon SageMaker AI with the AWS vLLM-Omni Deep Learning Container and stream generated speech over a persistent bidirectional connection. This Part 1 tutorial deploys Qwen3-TTS and streams speech through a Gradio application.
Deploy two generative media models from one AWS vLLM-Omni Deep Learning Container on Amazon SageMaker AI. Generate an image with FLUX.2-klein through real-time inference, then animate it into video with Wan2.1-VACE through asynchronous inference, and retrieve the MP4 from Amazon S3.
We benchmarked Claude Sonnet 5.5 for AI code review against Sonnet 5 and Opus 5.5: which bugs it catches, how fast it reviews, and what a review costs.
Most AI compute still runs on data centers built for websites and databases, and you pay for that overhead in every GPU-hour. Runware runs on Sonic Pods: low footprint, high efficiency modular AI data centers they design and build themselves, with the first wave coming online now.
There's no qwen3.7 on Ollama. 3.7 is API-only. Run Qwen 3.8 27B locally instead: VRAM by quant, Modelfile, num_ctx and tool calling.
To run a System One model locally, pick a runtime too: Ollaya serves ten open model families, laya-mlx runs Laya on Apple silicon, and llama.cpp needs a shim.
Optimize Mistral-7B deployment with Runpod by using quantized GGUF models and vLLM workers, compare GPU performance across pods and serverless endpoints.
Learn how to optimize your serverless GPU deployment on Runpod to balance latency, performance, and cost. From active and flex workers to Flashboot and.
Runpod's serverless platform keeps evolving, especially for LLM workloads. Learn what's new in 2025 and how to get the most from scalable deployments.
New to serverless? This guide shows you how to deploy a basic "Hello World" API on Runpod Serverless using Docker, perfect for beginners testing their.
Confused about spot vs. on-demand GPU instances? This guide breaks down the key differences in availability, pricing, and reliability so you can choose.
Deploy large language models like LLaMA or Mixtral on Runpod Serverless with strong privacy controls and no infrastructure headaches. Here’s how.
Showing 162 of 261 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts