
Maximem18 min read
AI Agent Evals: The Judge Is The Part Nobody Measures
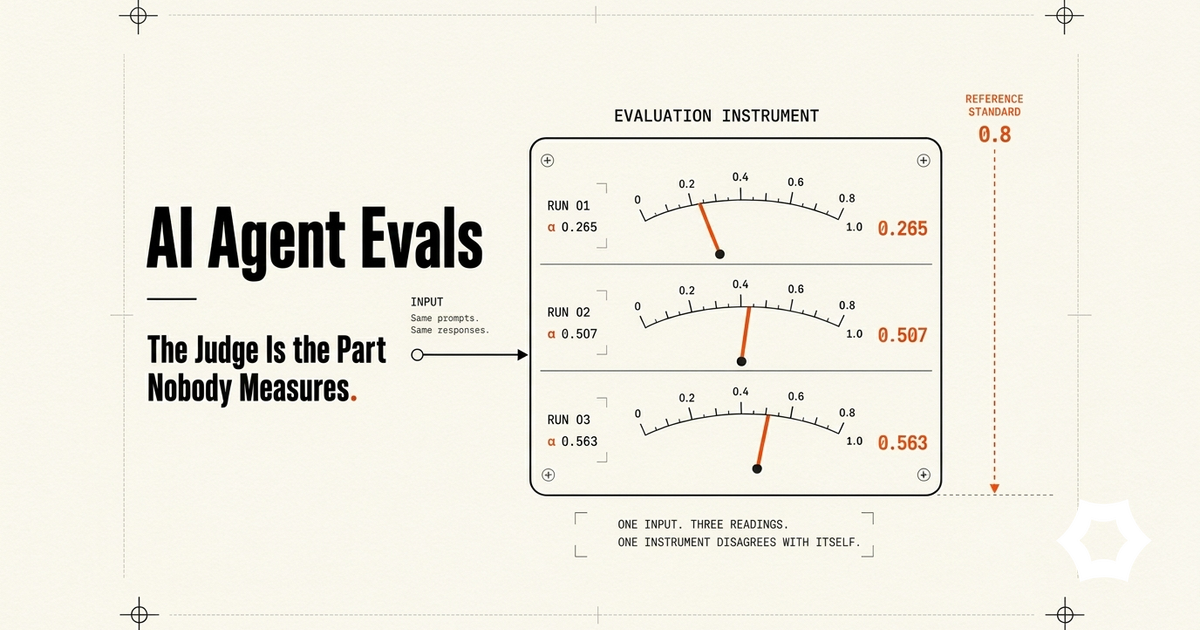
An LLM judge scoring the same agent output three times will often hand back three different answers, and almost no guide to agent evaluation asks whether the judge agrees with itself or what it costs to run on everything rather than a sample.
By Gaurav DadhichMaximem Synap Blog
Read the full story
Originally published by Maximem Synap Blog on Sep 18, 2026.
Comments
Sign in to join the discussion.