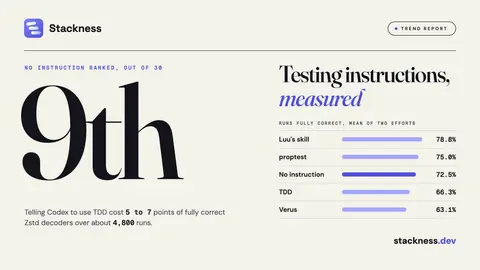
Do testing instructions improve coding agent correctness? What 30 conditions on one Zstd task measured
In a 30-condition eval, telling Codex to use TDD cut fully correct Zstd decoders by 5 to 7 points. No testing instruction clearly beat none.
12 stories
In a 30-condition eval, telling Codex to use TDD cut fully correct Zstd decoders by 5 to 7 points. No testing instruction clearly beat none.
Automated evals can score every agent session, but they do not automatically reflect what your team considers a good outcome. That takes human judgment. The post Alignment is a human-AI workflow: how Custom Views make agent review possible appeared first on Arize AI.
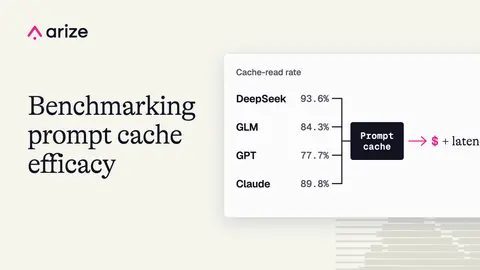
We benchmarked prompt caching across DeepSeek, GLM, GPT, and Claude using Harbor evals and Phoenix traces, so we could compare cache reuse, estimated cost, and latency on the same multi-turn shopping assistant agent.
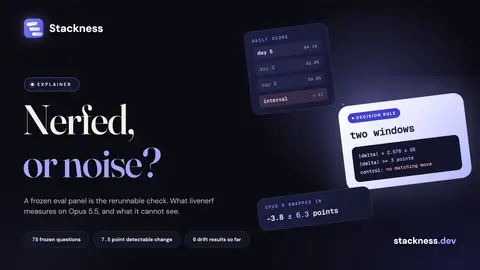
A frozen eval panel is the only rerunnable way to tell whether a hosted model got worse. What livenerf measures on Opus 5.5, and how to size your own.
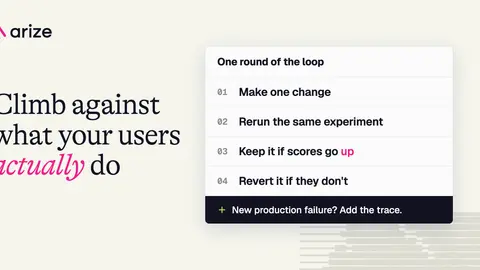
Anthropic's Claude hillclimb loop designs evals and improves agents one change at a time. Here's how to run that loop against production traces in Arize AX. The post Claude’s hillclimb loop for AI agents: start with production traces appeared first on Arize AI.
Agents built and deployed on MongoDB’s Atlas Agent Engine can export OpenTelemetry traces to Arize AX, where teams can inspect each run, evaluate both the outcome and execution path, and test fixes before redeploying.
Opus 5.5 dropped em dashes from 12.9 per 1,000 words to two in 57,000 words, and cut the rest of the Claudisms in half. Better, but not fixed. The post Anthropic says it fixed Claude’s writing. I ran the evals to check. appeared first on Arize AI.
Sessions are now a first-class unit of work in Arize AX. Annotate a whole conversation, queue it for review, and ask Alyx to filter for it — plus Agent-as-a-Judge on every plan, vision judges, faster datasets, and everything else that shipped between August 6 and September 18, 2026.
Last week TypeSafe AI unveiled Jev, their first example of a new category of model that they are calling "System One models" (I'm with Maggie Appleton, I think "decision models" is a better name for these).
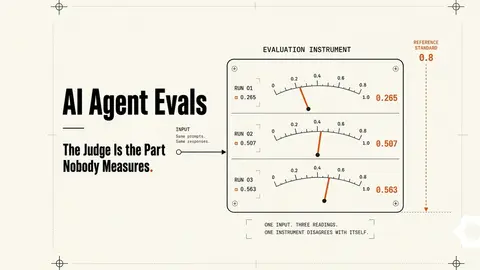
An LLM judge scoring the same agent output three times will often hand back three different answers, and almost no guide to agent evaluation asks whether the judge agrees with itself or what it costs to run on everything rather than a sample.
Providing a complete evaluation system for Fin, you can now test changes before they go live, roll them out with control, evaluate every live conversation, and have confidence in the experience Fin delivers.
OpenAI recently announced they're opening the ChatGPT app store for app submissions. Learn how to pass test cases with MCPJam's evals platform.
Showing 12 of 12 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts