
CoT10 min read
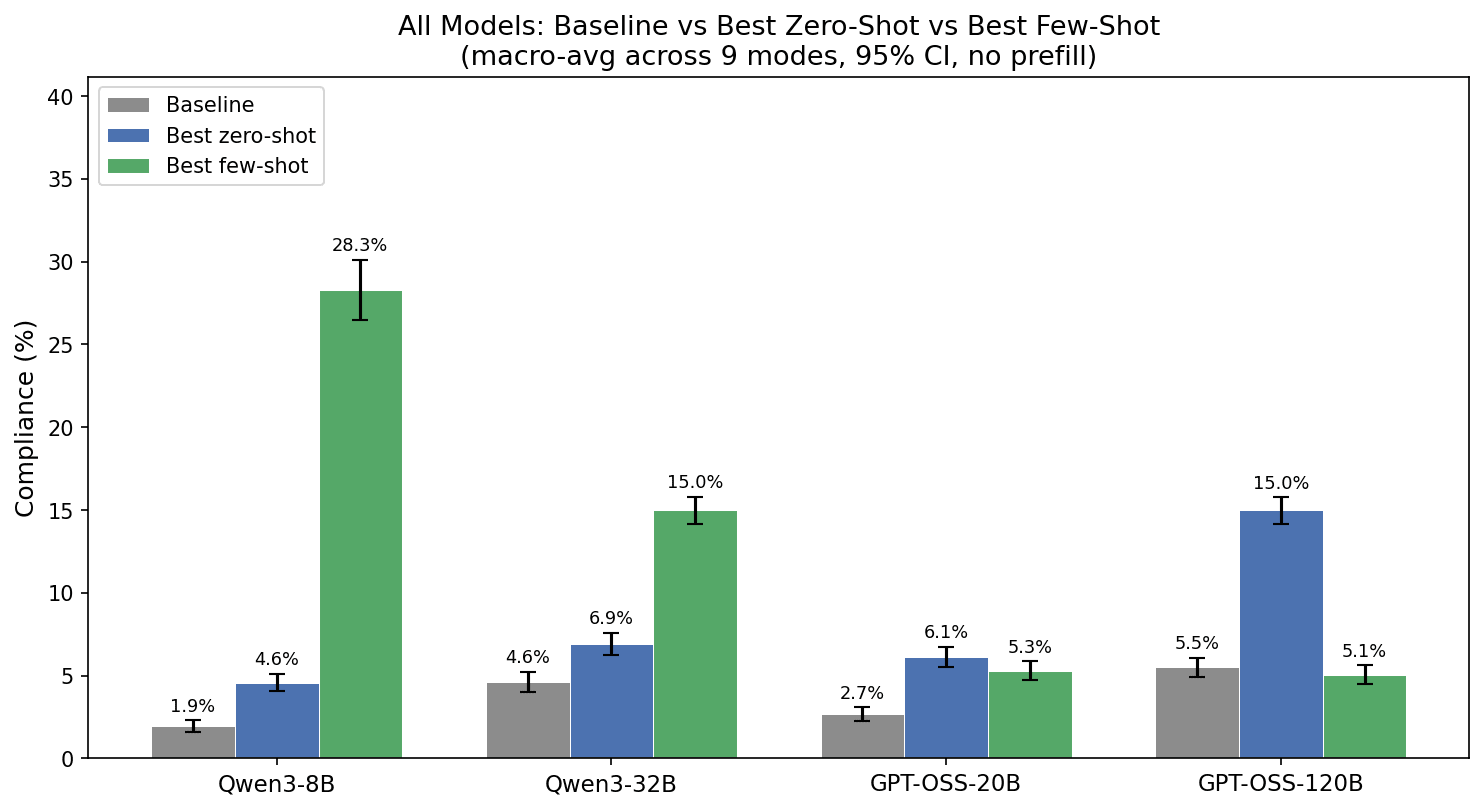
CoT controllability evals seem very under-elicited
The CoTControl eval asks reasoning models to follow formatting constraints in their chain-of-thought (e.g. write in all lowercase, avoid a specific word) while solving questions. Models seem to mostly be pretty bad at this: recent models score between 0-30% with the exception of Mythos Preview[1].
By JozdienAlignment Forum
Read the full story
Originally published by Alignment Forum on Sep 11, 2026.
Comments
Sign in to join the discussion.