
Stackness10 min read
Multi-model agent team vs a single frontier model: what the Memdoor claim measures, and the cost per task
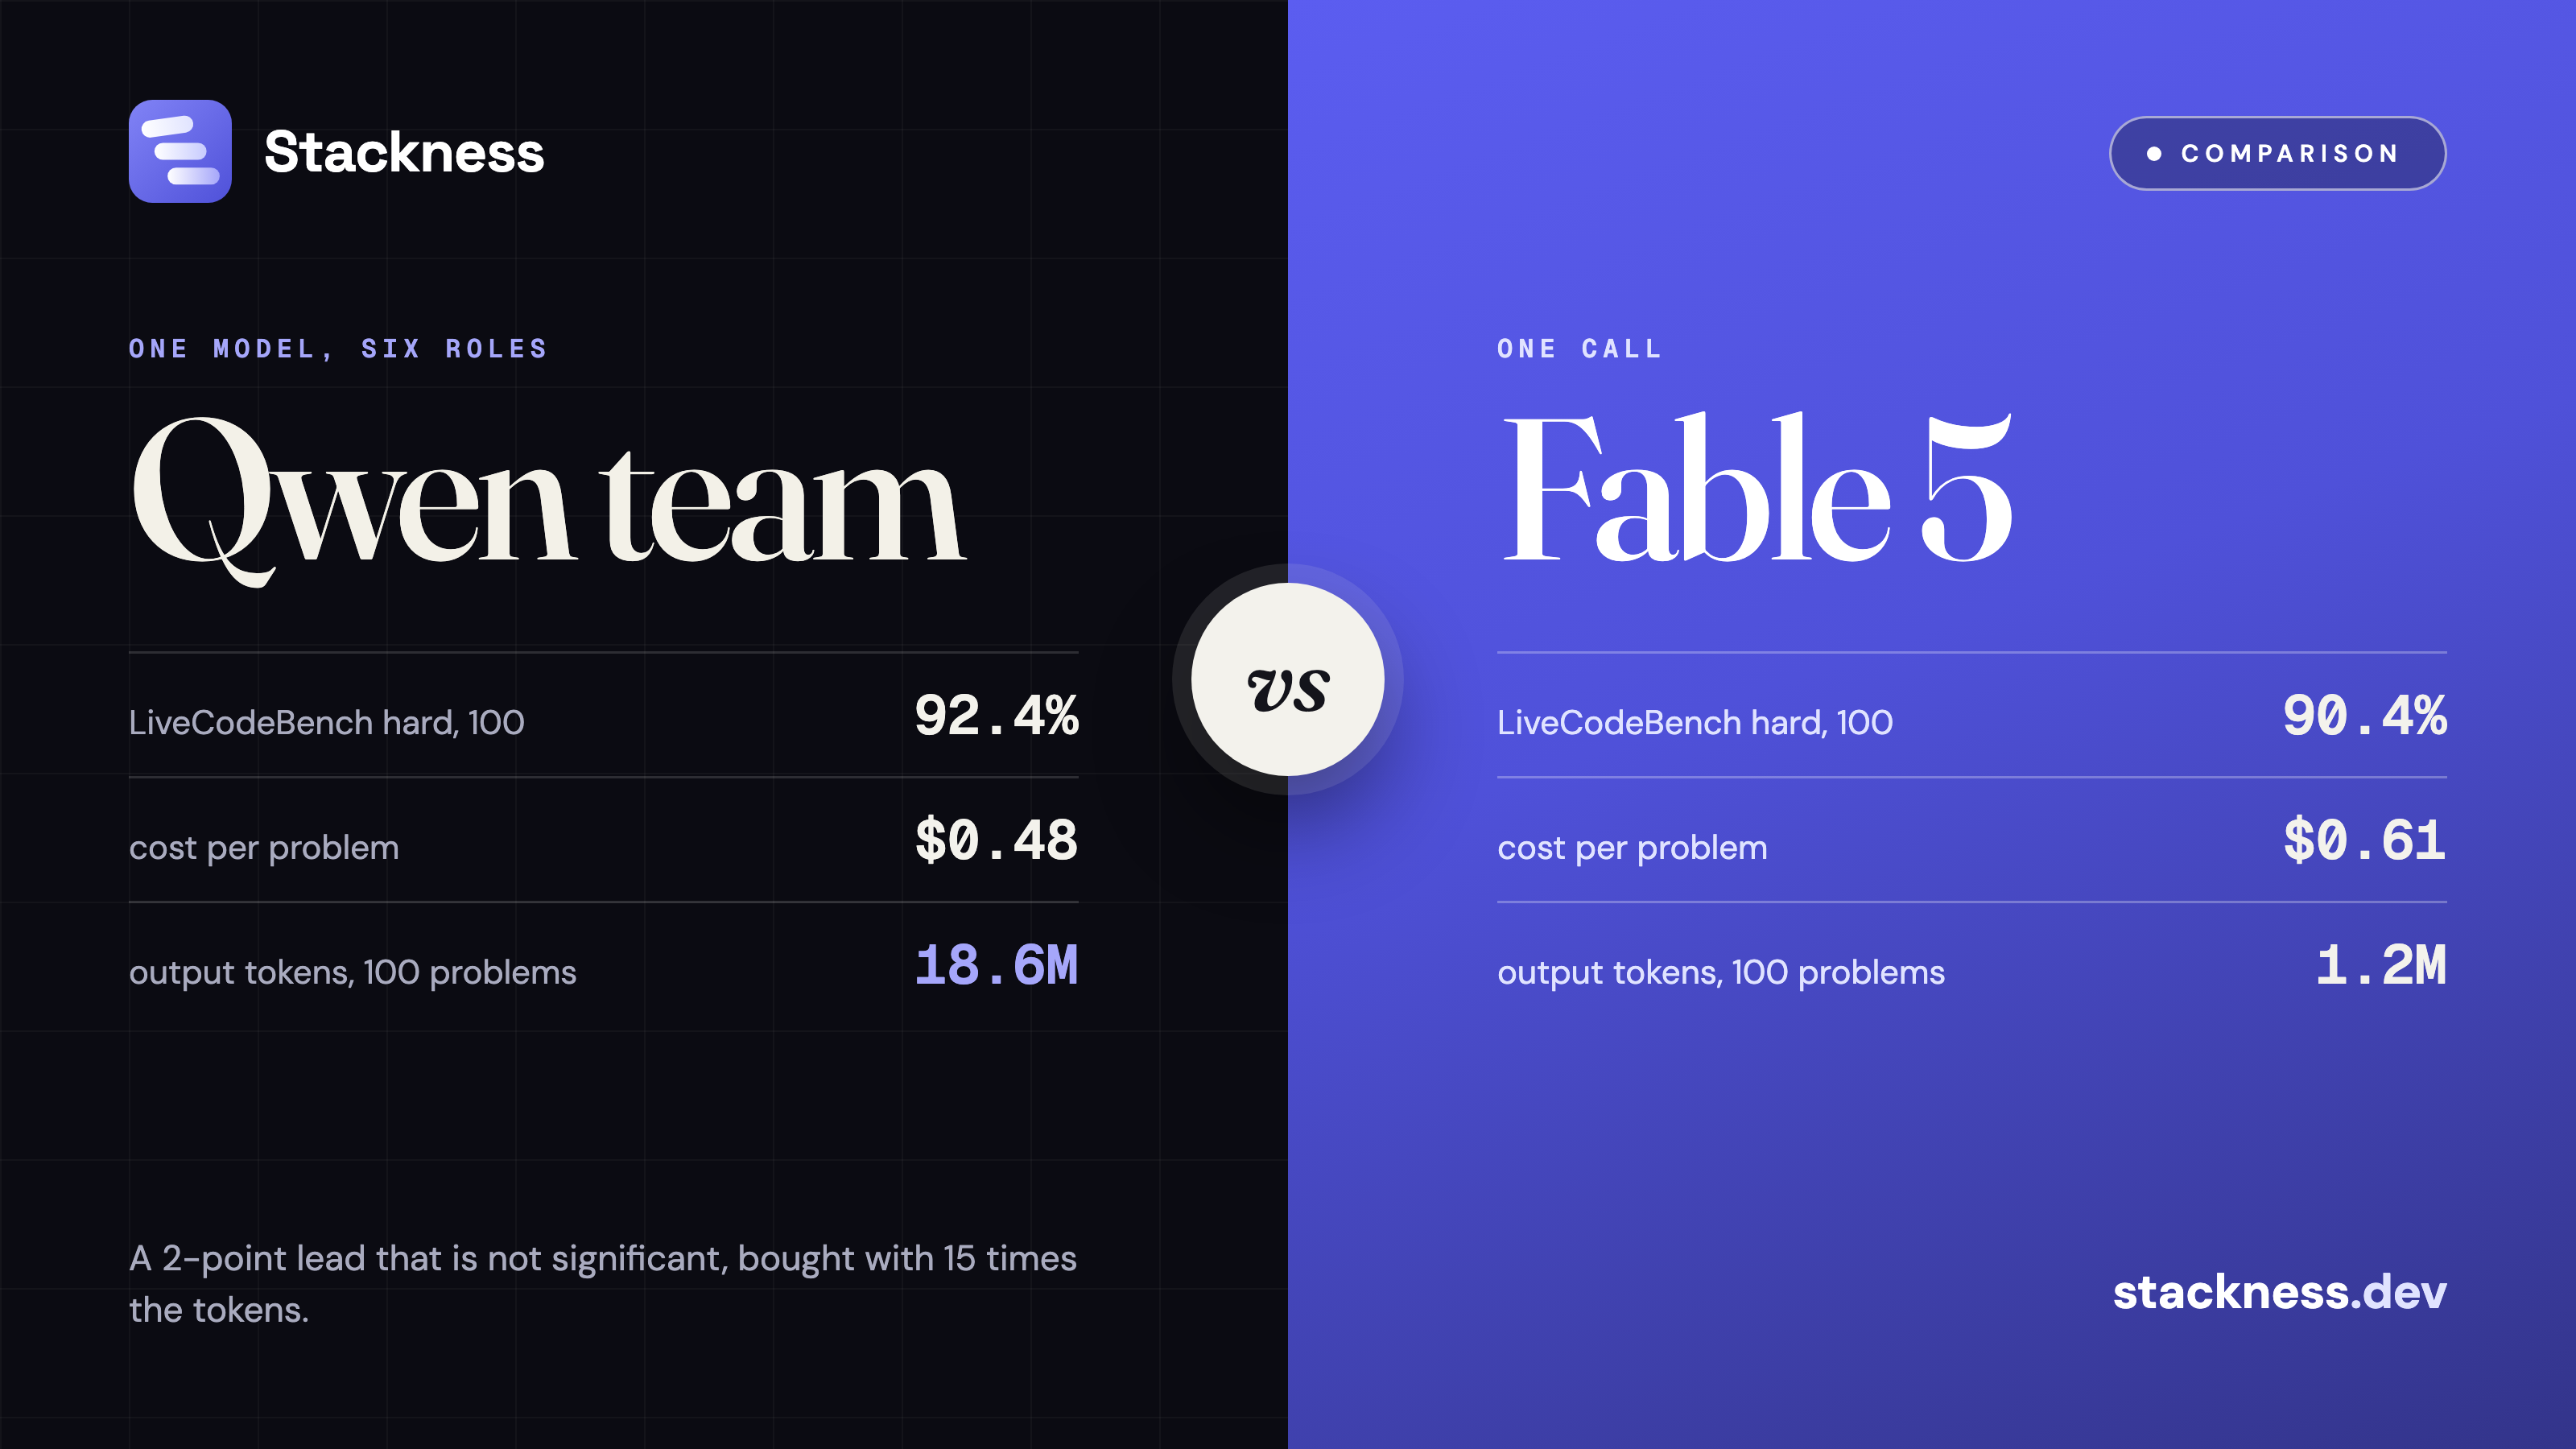
A loop of Qwen3.8-27B calls scored 92.4% to Fable 5's 90.4% on hard LiveCodeBench, not a significant gap, at $0.48 vs $0.61 a task and 15x the tokens.


By Sergei GordeichukStackness Blog
Read the full story
Originally published by Stackness Blog on Nov 1, 2026.
Comments
Sign in to join the discussion.