
Generative AI7 min read
NVIDIA Shows 3 Ways to Speed Up MoE Inference on DGX Spark, Lifting Ling-3.0-flash Throughput 42.5%
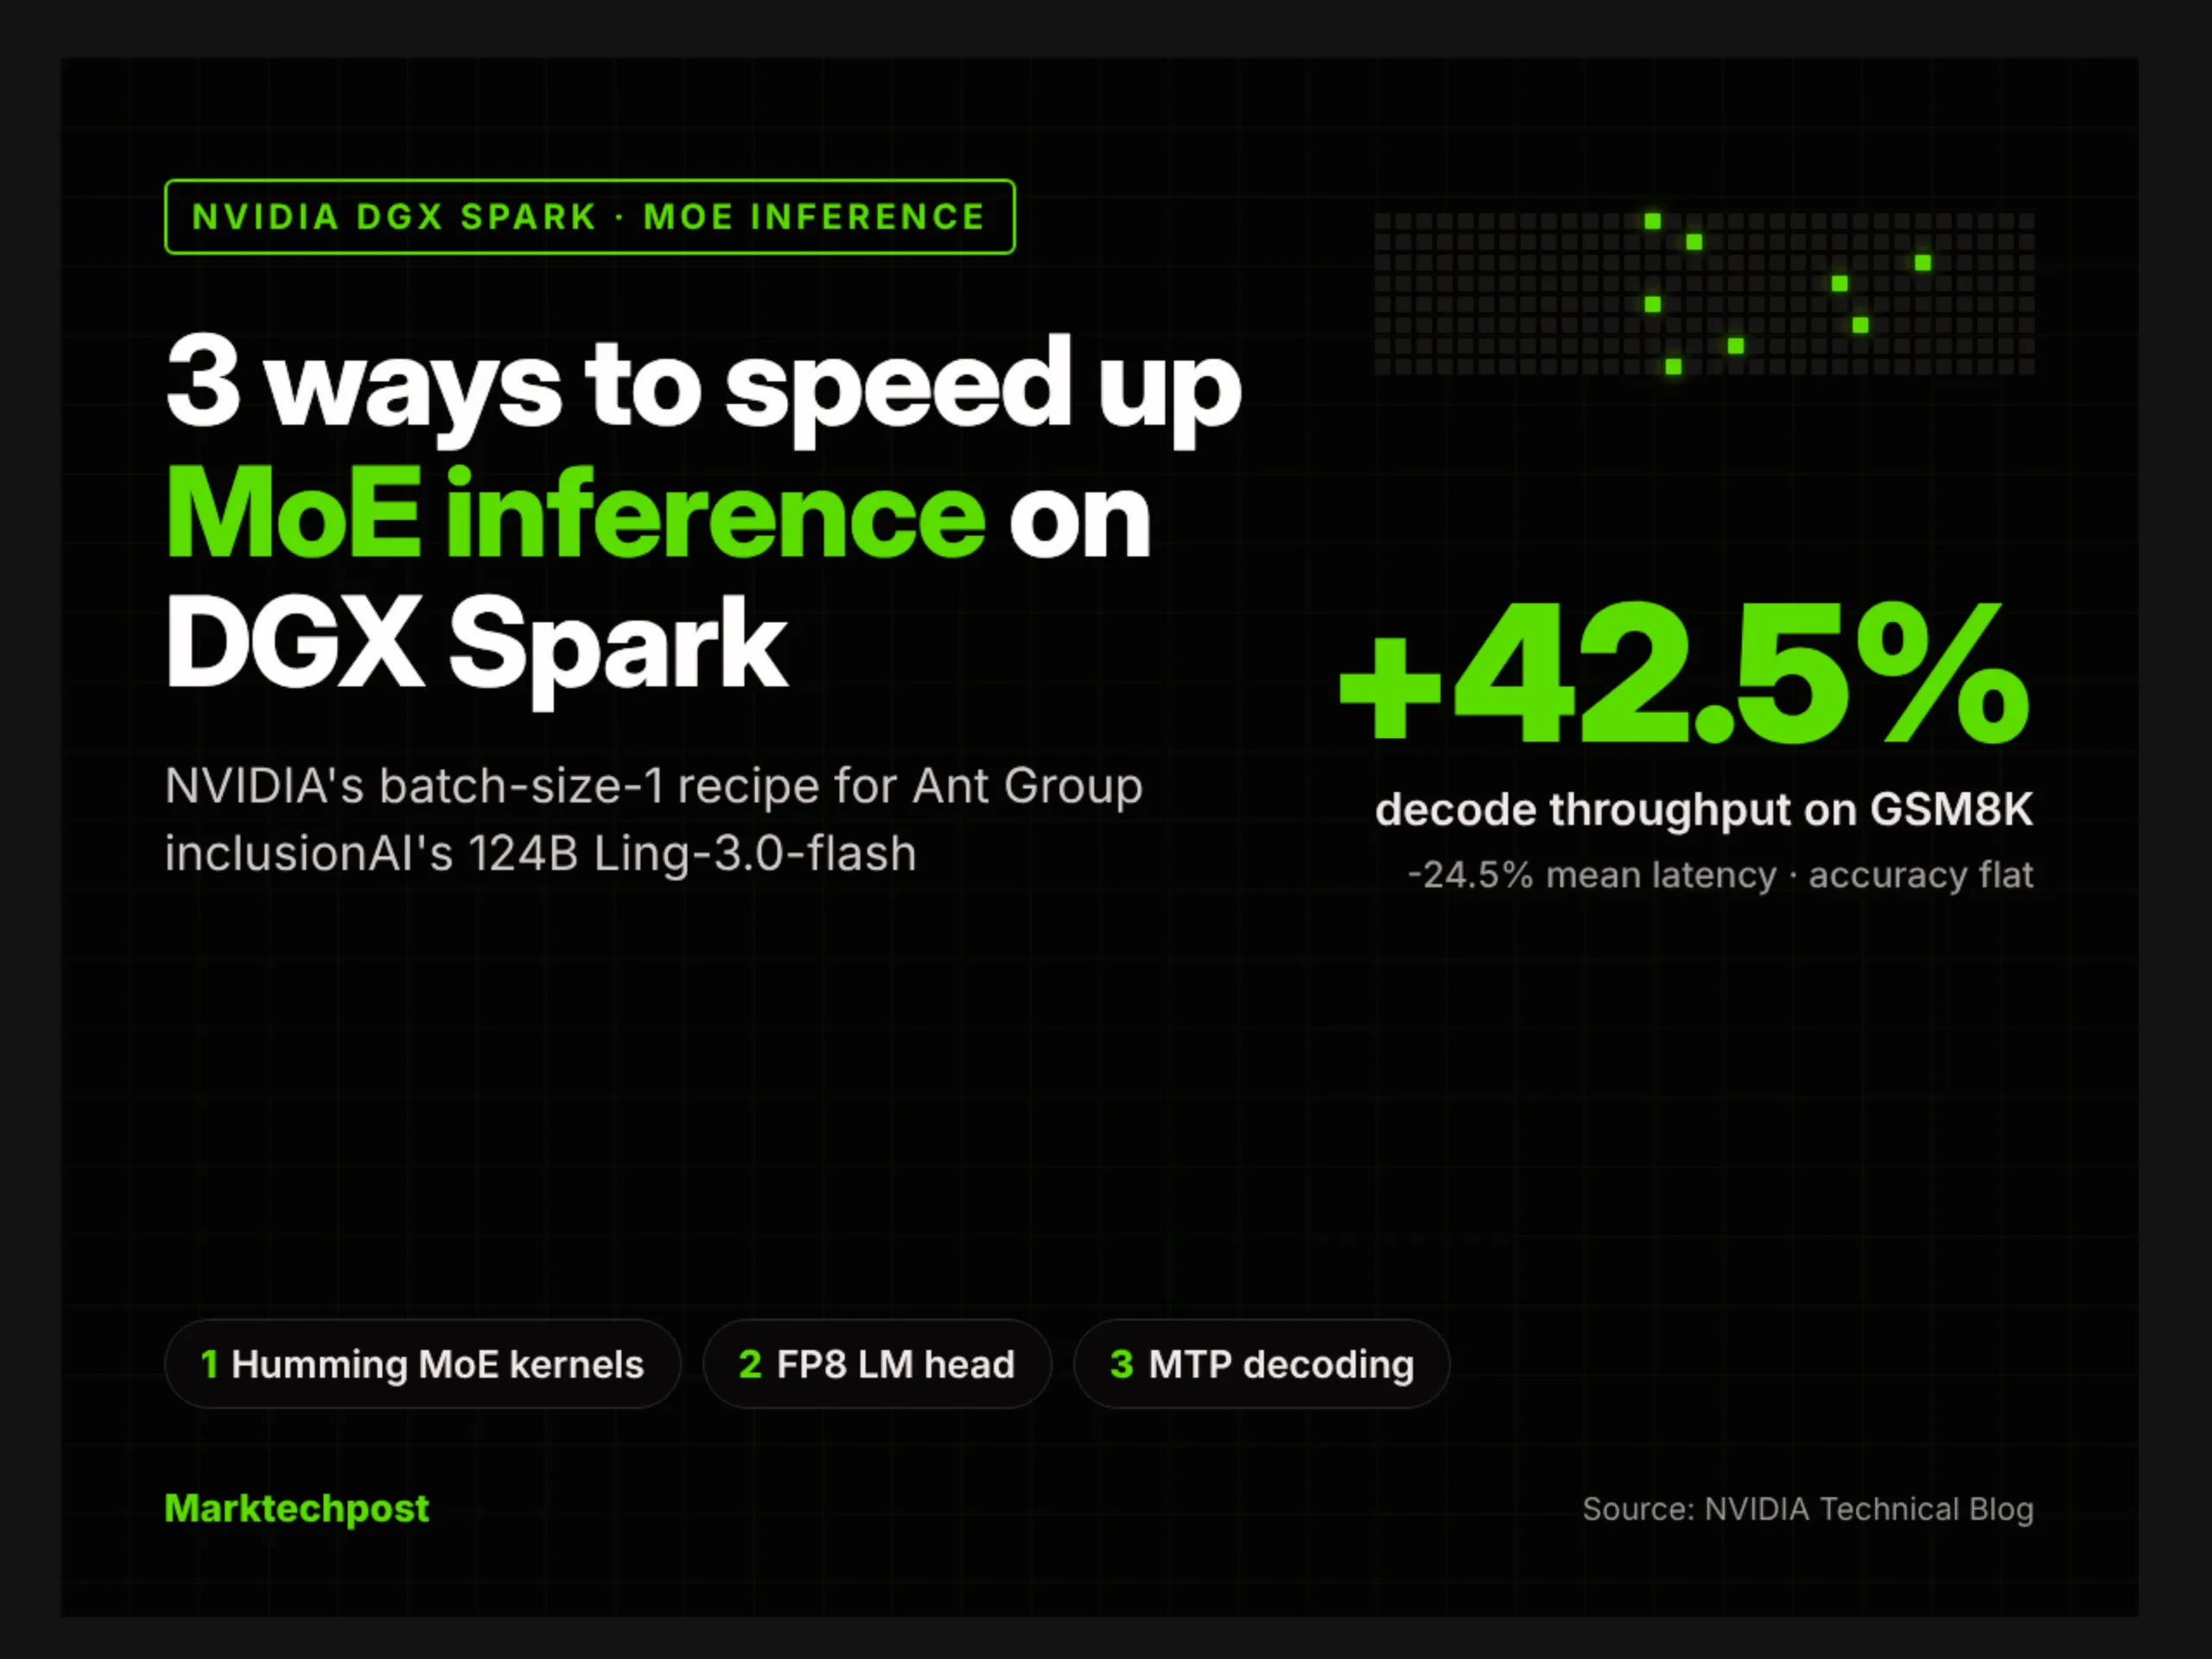
NVIDIA shows how 3 stacked optimizations speed up MoE inference on a single DGX Spark. On Ant Group inclusionAI's 124B Ling-3.0-flash, GSM8K decode throughput rose 42.5% with no detectable accuracy change.


By Asif RazzaqMarkTechPost
Read the full story
Originally published by MarkTechPost on Nov 3, 2026.
Comments
Sign in to join the discussion.