
RunInfra
Serves open models with fast responses and lower-cost cached context.
- Paid· from $10/month
- Web
- API Available
What is RunInfra?
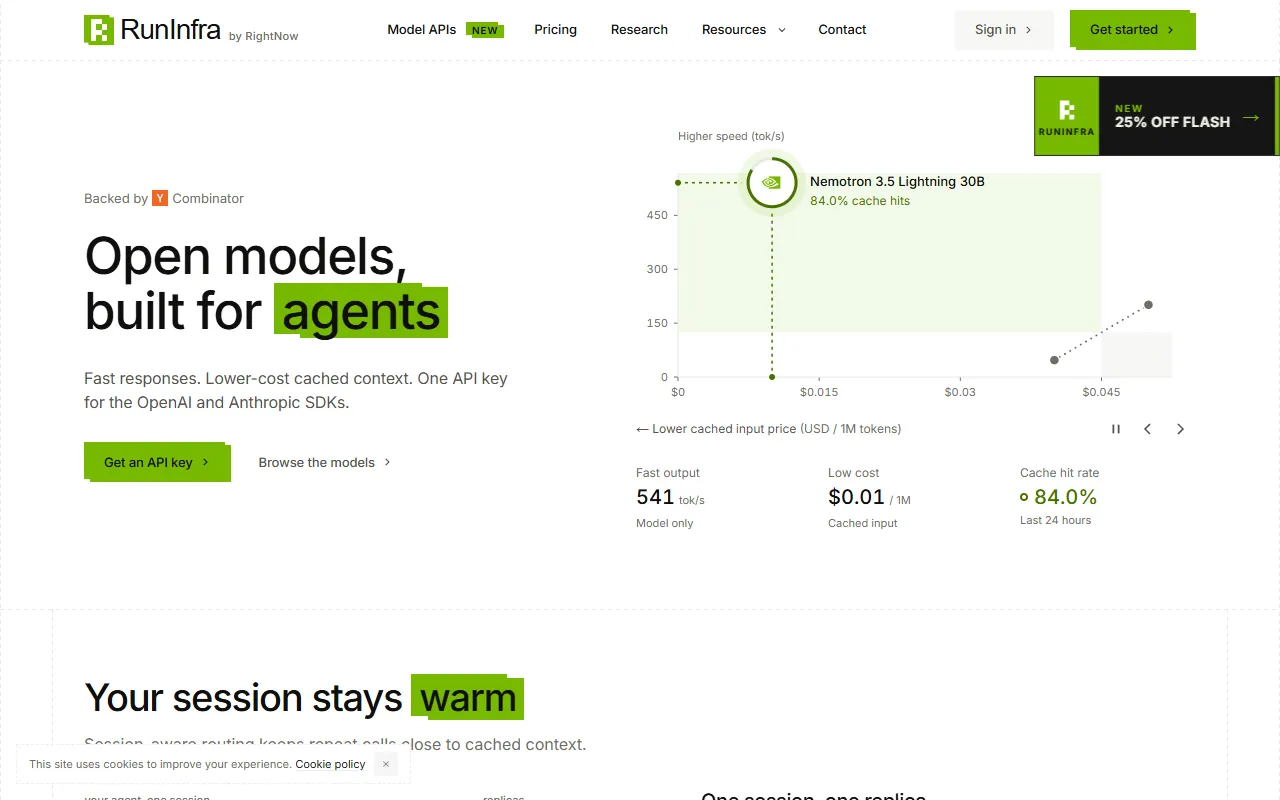
RunInfra is an AI APIs tool that serves open models with fast responses and lower-cost cached context. RunInfra is a paid tool, starting at $10/month. It is available on Web App. It is aimed at developers, teams and ai engineers.
RunInfra provides APIs for open models with fast response times, lower-cost cached context, and a single API key for OpenAI and Anthropic SDKs. It is designed for developers and teams needing efficient model inference solutions.
Built for developers, teams and ai engineers.
Key capabilities
Features
Inference Speed
Improves response times for model queries.
Cost Management
Reduces costs through cached context.
Session Management
Model Library
Hosted APIs
Provides hosted model APIs without storing prompts.
Encryption
Use cases
- Deploy production APIs for open models
- Optimize model inference costs and speed
- Manage sessions for continuous model use
Who it's for
Pros & cons
Pros
- Public API available
- No free plan, paid plans from $10/month
- Usage-based pricing with monthly coding plans
- SOC 2 Type II compliance
Cons
No documented limitations yet.
Pricing
Paid — paid plans start at $10/month.
| Plan | Price |
|---|---|
| Pay as you go | $5 |
| Enterprise | Custom |
| Starter | $10 / month |
| Pro | $29 / month |
| Team | $99 / month |
| Choose a plan | $10 / month |
AI models
- DeepSeek V4.1
- Qwen 3.8
Developer & API
Public REST API available
- Authentication
- API Key, Bearer Token
- SDKs
- Python, TypeScript, cURL
Security & compliance
- SOC 2
- SSO
- Two-factor authentication
- Encryption
- Data deletion
As stated on RunInfra's website — not independently verified by AiByts.
FAQ
What is RunInfra?
RunInfra is an AI APIs tool that serves open models with fast responses and lower-cost cached context. RunInfra provides APIs for open models with fast response times, lower-cost cached context, and a single API key for OpenAI and Anthropic SDKs. It is designed for developers and teams needing efficient model inference solutions.
Is RunInfra free?
No, RunInfra is a paid tool.
How much does RunInfra cost?
RunInfra offers 6 plans: Pay as you go ($5), Enterprise (Custom), Starter ($10 / month), Pro ($29 / month), Team ($99 / month) and Choose a plan ($10 / month).
Does RunInfra have an API?
Yes, RunInfra offers a public REST API for building custom integrations.
What platforms does RunInfra support?
RunInfra is available on Web App.
Who should use RunInfra?
RunInfra is built for developers, teams and ai engineers. Common uses: deploy production APIs for open models, optimize model inference costs and speed and manage sessions for continuous model use.
What are the best alternatives to RunInfra?
Similar tools on AiByts include ZeroGPU, Groq Cloud, Social Fetch, Forsy and Respira for WordPress.
RunInfra news & updates
RunInfra is now inference for agents
RunInfra now focuses on hosted inference for agents, with pay-as-you-go Model APIs and setup guides for Claude Code, Codex and other coding agents.
RunInfra Blog1 min read
With software alone, one B200 beats the LPU and gets close to Cerebras
Stock SGLang served gpt-oss-120b at 411 tokens per second on one rented B200. Four settings took the same card and the same weights to 1,366, and single prompts to 2,215. No kernel written, nothing recompiled.
RunInfra Blog17 min read
Lossless Inference
How to make LLM serving faster without touching the model. Exact kernels, speculative decoding, lossless compression, KV reuse and scheduling, with the math and how to verify it with logit parity.
RunInfra Blog8 min read
The fastest way to serve DeepSeek V4 Flash
Historical measurements published August 2, 2026 for DeepSeek V4 Flash 0731 on four B200 GPUs. As of September 21, 2026, no current measured optimization package is published for it.
RunInfra Blog8 min read
$0.09 and $290.12: What Actually Moves Your Inference Bill
Nine cents and $290.12 are both prices for one million output tokens. The gap is driven by accelerator, provider, concurrency, utilization, and reasoning token volume.
RunInfra Blog10 min read
Serving Kimi K3 on vLLM was hard. Here is what we measured.
No released vLLM build served Kimi K3 when we started. We resolved several distinct failures on 8x B300 and measured the result, its operating crossover, and its honest limits.
RunInfra Blog10 min read
vLLM vs SGLang vs TensorRT-LLM: a serving benchmark
Self-reported Llama-3.1-8B results for three LLM inference engines. Published unique-prompt throughput and latency rows cover H100 bf16. FP8 and L40S appear only in derived cost results. The harness and raw data are not publicly available.
RunInfra Blog9 min read
Details are compiled from RunInfra's website and public sources, last verified Oct 6, 2026. Features and pricing change — confirm on the official site before you buy.
Try RunInfra
Paid · from $10/month
Tags
- Open Models
- Model APIs
- Inference Speed
Comments
Sign in to join the discussion.