Know a great AI tool or AI news source? Submit it to AiByts

Agent Evaluation

30 stories

Stories

  • AI harness crash course

    The model can write the code. It can't open your files, run your tests, or ask before doing something risky. The software that does all of that is the AI harness, and this crash course shows you how to design one.

    Google Cloud Tech
  • EU AI Act compliance for AI agents: a practical engineering guide

    Learn how agent traces, human oversight, production evaluations, and log retention support EU AI Act compliance with a practical credit-assistant example. The post EU AI Act compliance for AI agents: a practical engineering guide appeared first on Arize AI.

    Arize Phoenix14 min read
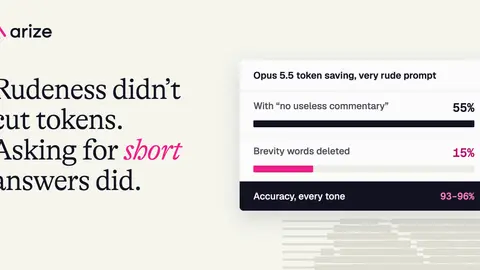
  • Does being rude to AI work? What 6 models revealed

    Does being rude to AI improve answers or lower costs? We tested six models to separate prompt tone from brevity instructions and examine what changes. The post Does being rude to AI work? What 6 models revealed appeared first on Arize AI.

    Arize Phoenix15 min read
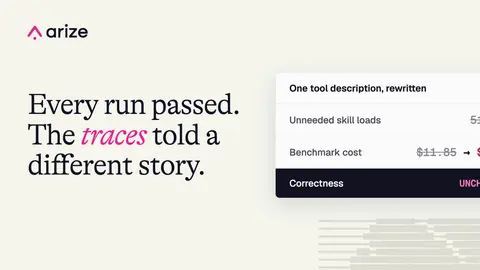
  • How to test agent tool descriptions with Harbor and Phoenix

    Build a reproducible benchmark, compare tool use across agents, and test whether a description change reduces unnecessary work while preserving outcomes. The post How to test agent tool descriptions with Harbor and Phoenix appeared first on Arize AI.

    Arize Phoenix9 min read
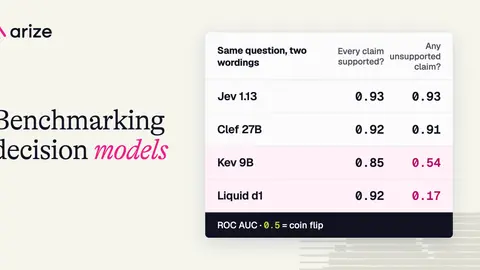
  • Decision model benchmark: Jev, Kev, Liquid d1, and more

    On 15 September, TypeSafe released Jev, and within a few weeks about 10 companies had shipped something that works the same way. OpenAI, Liquid, Cloudflare, AWS and PostHog all launched one, and an open clone called Kev showed up on Hugging Face in between.

    Arize AI14 min read
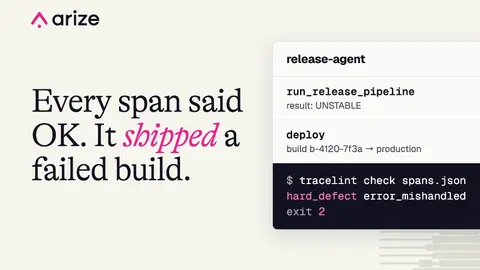
  • What agent traces can tell you without an LLM judge

    Some agent failures are already in the trace. tracelint proves them on Phoenix OpenInference spans and fails CI, without an LLM judge. The post What agent traces can tell you without an LLM judge appeared first on Arize AI.

    Arize AI7 min read
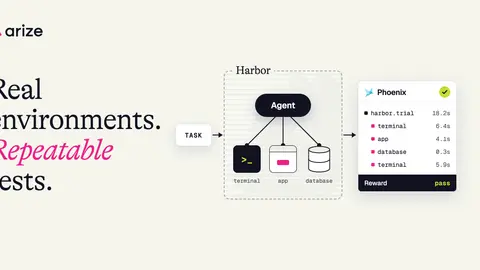
  • How we benchmark AI agents and tools with Harbor and Arize Phoenix

    See how Arize uses Harbor and Phoenix to benchmark AI agents, MCP servers, skills, and CLIs in reproducible sandboxes, then inspect traces and annotations. The post How we benchmark AI agents and tools with Harbor and Arize Phoenix appeared first on Arize AI.

    Arize Phoenix5 min read
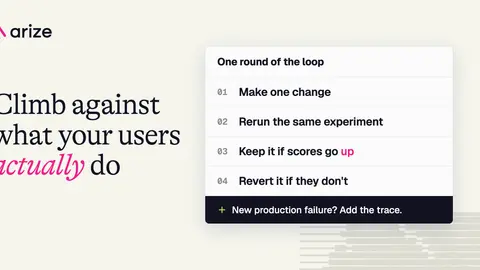
  • Claude’s hillclimb loop for AI agents: start with production traces

    Anthropic's Claude hillclimb loop designs evals and improves agents one change at a time. Here's how to run that loop against production traces in Arize AX. The post Claude’s hillclimb loop for AI agents: start with production traces appeared first on Arize AI.

    Arize AI12 min read
  • Are agent harnesses dying? What harness distillation changes

    Harness distillation can train general scaffolding into a model. The harness that remains is the part tied to your tools, data, users, and environment. The post Are agent harnesses dying? What harness distillation changes appeared first on Arize AI.

    Arize AI9 min read
  • Evaluate production traces with Jev-as-a-Judge directly in Arize AX

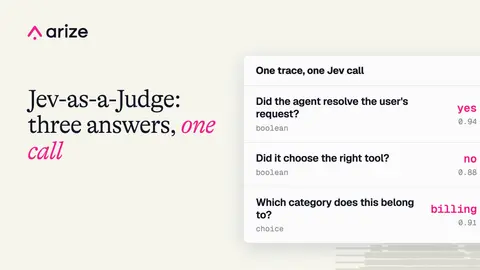
    Arize AX now integrates directly with TypeSafe AI, bringing native Jev-as-a-Judge evaluations into the Arize evaluation workflow. The post Evaluate production traces with Jev-as-a-Judge directly in Arize AX appeared first on Arize AI.

    Arize AI3 min read

Showing 18 of 30 stories

Load more stories
AiByts Weekly Brief

Get the top AI news and tools straight to your inbox every week.

Weekly · AI news

Join 15,000+ AI enthusiasts