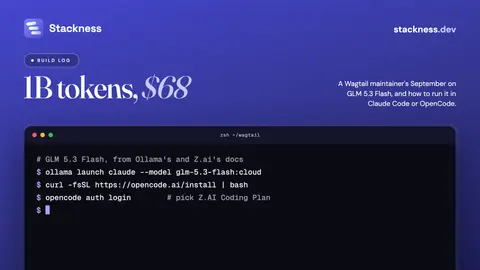
GLM 5.3 Flash as a coding agent: a month of daily use, $68, and the slot it kept
A Wagtail maintainer ran 1B tokens of GLM 5.3 Flash in September for $68 and kept it as the default for 95% of tasks. The costs, the setup and what breaks.
63 stories
A Wagtail maintainer ran 1B tokens of GLM 5.3 Flash in September for $68 and kept it as the default for 95% of tasks. The costs, the setup and what breaks.
Release: llm-openai-decisions 0.1a0 OpenAI released their new Jev-style Decisions API, as previously announced at last week's DevDay. Since I already have an llm-typesafe plugin for talking to Jev, I had GPT-6 Astra read the new OpenAI API documentation and build an llm-openai-decisions plugin…
Google LLC today released EmbeddingGemma 2, an open multimodal embedding model small enough to run on a smartphone. The release takes the EmbeddingGemma line beyond text, which was all the first version handled when Google introduced it in September 2025.
DeepSeek Harness runs any provider's model, Claude Code only Claude's. The lock-in sits in plugins, hooks, sessions and config, and those do not move.
Commit on green, keep every caller with its change, and stack small pull requests. The diff-size numbers behind it, and the hooks that enforce it.
Memory is what an agent noted and a plugin replays. Documentation is what you wrote, reviewed and committed. How each loads, and what to write down.
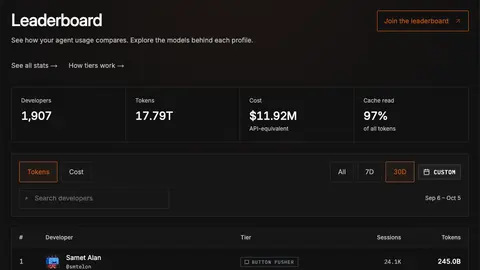
See how your agent usage stacks up. Then challenge a friend.
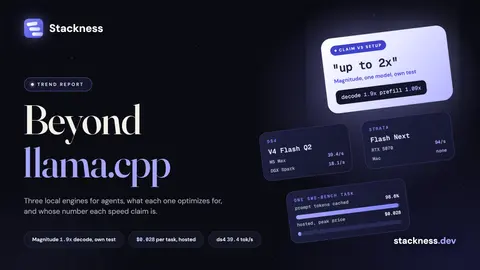
ds4 runs big MoE models on 96 GB Macs, Magnitude tunes kernels to your device, Strata puts one model on a gaming PC. Every speed claim is self-reported.
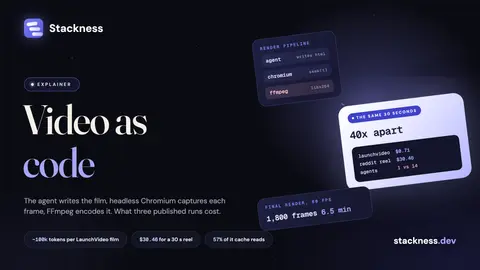
The agent writes the film as code, headless Chromium captures each frame, FFmpeg encodes. LaunchVideo spends 100k tokens a film; a 14-agent reel cost $30.46.
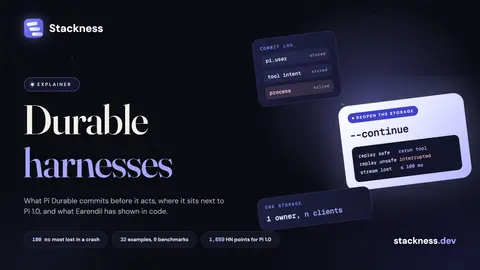
A durable harness commits every step of an agent run to storage, so a crash resumes mid-turn. What Pi Durable shipped on 1 October, and what is only claimed.
Sonnet 5.5 costs half of Opus 5.5 per token, but cache reads cost $0.20 on both. Which model plans, which one edits, and what one metered run saves.
A frozen eval panel is the only rerunnable way to tell whether a hosted model got worse. What livenerf measures on Opus 5.5, and how to size your own.
An ADE is an app built around tasks that coding agents run, not files you edit. What JetBrains Air shipped, and whether an ADE replaces your IDE.
Opus 5.5 sends its between-tool notes as empty thinking blocks and ends some turns early. What breaks in an agent harness, and the documented fixes.
I'm at OpenAI DevDay today, in Fort Mason, San Francisco. Same as last year I'll be live blogging the keynote and some other notes during the day. OpenAI gave me a free ticket and a seat in the "creator" area for the keynote. Tags: ai, openai, generative-ai, llms, coding-agents, live-blog
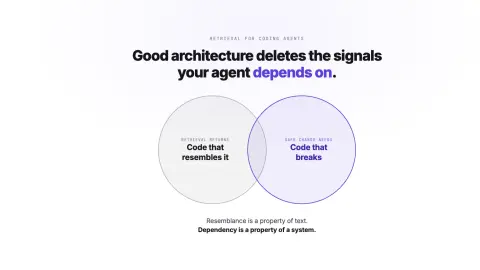
Every boundary you draw removes a signal your tooling was relying on. That is a structure problem, not a search problem. The post Good Architecture Deletes the Signals Your Agent Depends On appeared first on Towards Data Science.
RunInfra now focuses on hosted inference for agents, with pay-as-you-go Model APIs and setup guides for Claude Code, Codex and other coding agents.
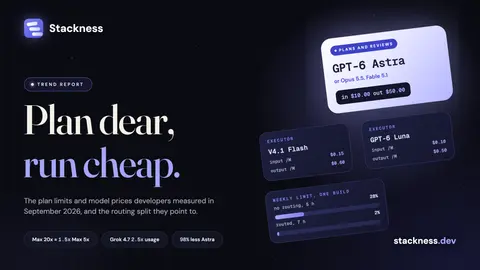
Model routing for coding agents in September 2026: a frontier model plans, a cheap one executes. The plan and price numbers developers measured.
Showing 36 of 63 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts