Know a great AI tool or AI news source? Submit it to AiByts

CoT

8 stories

Stories

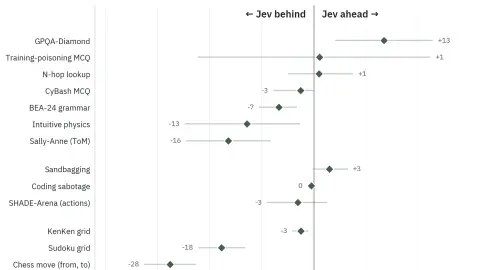
  • Benchmarking Jev against no-CoT LLMs

    TL;DR. We ran Jev 1.13 — TypeSafe's non-autoregressive model, which answers questions with probabilities and cannot emit text, on the ThinkFast no-CoT suite and Neel Nanda’s NCRI.Jev’s capabilities are very jagged.

    LessWrong8 min read
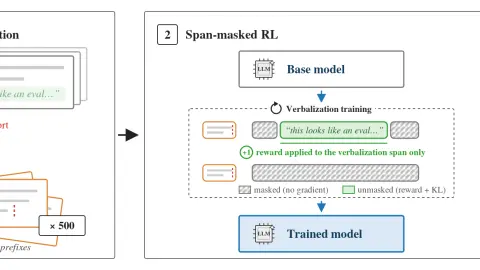
  • Improving CoT Monitorability of Evaluation Awareness via Verbalization Training

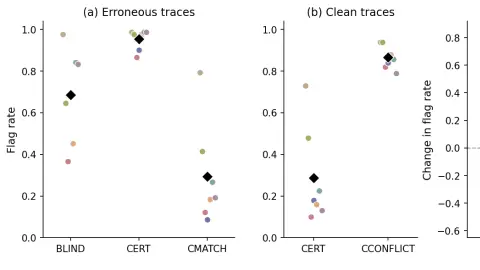
    This is joint work with Sahar Abdelnabi and David Krueger. It is mostly a linkpost for the paper (https://arxiv.org/abs/2609.36316) but also contains some additional commentary on CoT monitorability.TL;DR: Verbalization training makes a model less reticent about verbalizing a belief it already…

    LessWrong18 min read
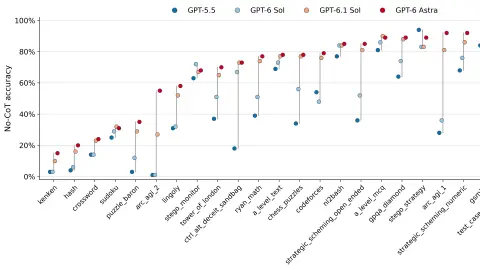
  • CoT controllability evals seem very under-elicited

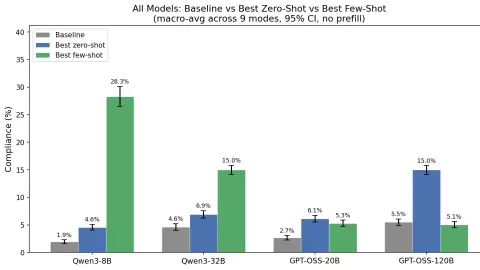
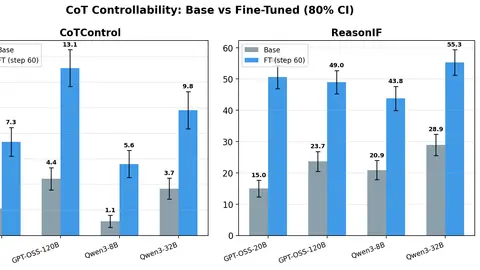
    The CoTControl eval asks reasoning models to follow formatting constraints in their chain-of-thought (e.g. write in all lowercase, avoid a specific word) while solving questions. Models seem to mostly be pretty bad at this: recent models score between 0-30% with the exception of Mythos Preview[1].

    Alignment Forum10 min read
  • Fine-tuning experiments on CoT controllability

    We find that a small amount of fine-tuning on instruction following in the CoT generalizes to meaningful increases in CoT controllability on an out-of-distribution set of tasks.

    METR11 min read

Showing 8 of 8 stories

You're all caught up.

AiByts Weekly Brief

Get the top AI news and tools straight to your inbox every week.

Weekly · AI news

Join 15,000+ AI enthusiasts