Know a great AI tool or AI news source? Submit it to AiByts

Evaluations

9 stories

Stories

  • EU AI Act compliance for AI agents: a practical engineering guide

    Learn how agent traces, human oversight, production evaluations, and log retention support EU AI Act compliance with a practical credit-assistant example. The post EU AI Act compliance for AI agents: a practical engineering guide appeared first on Arize AI.

    Arize Phoenix14 min read
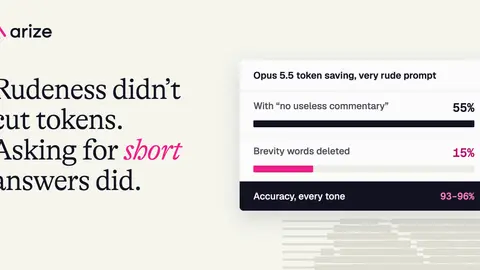
  • Does being rude to AI work? What 6 models revealed

    Does being rude to AI improve answers or lower costs? We tested six models to separate prompt tone from brevity instructions and examine what changes. The post Does being rude to AI work? What 6 models revealed appeared first on Arize AI.

    Arize Phoenix15 min read
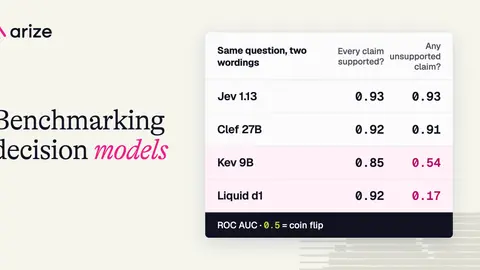
  • Decision model benchmark: Jev, Kev, Liquid d1, and more

    On 15 September, TypeSafe released Jev, and within a few weeks about 10 companies had shipped something that works the same way. OpenAI, Liquid, Cloudflare, AWS and PostHog all launched one, and an open clone called Kev showed up on Hugging Face in between.

    Arize AI14 min read
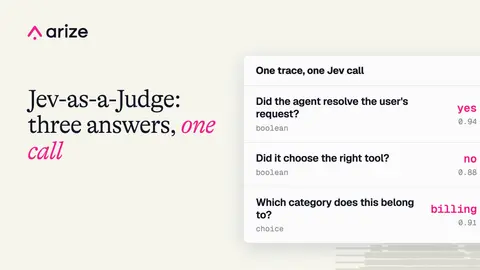
  • Evaluate production traces with Jev-as-a-Judge directly in Arize AX

    Arize AX now integrates directly with TypeSafe AI, bringing native Jev-as-a-Judge evaluations into the Arize evaluation workflow. The post Evaluate production traces with Jev-as-a-Judge directly in Arize AX appeared first on Arize AI.

    Arize AI3 min read
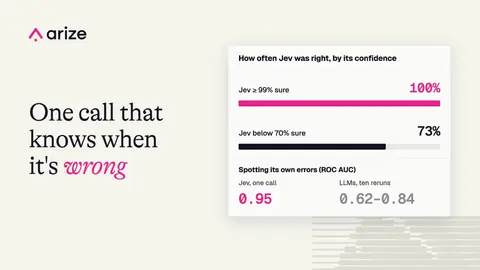
  • What Jev’s probabilities reveal that repeated LLM judgments miss

    I tested Jev and five LLM judges across ten Arize Phoenix evaluators to measure how often their answers changed alongside accuracy, cost, and latency. The post What Jev’s probabilities reveal that repeated LLM judgments miss appeared first on Arize AI.

    Arize AI12 min read
  • How to build a remote evaluator in Arize AX with Jev

    Evaluate agent responses with Jev and Arize AX. Build a FastAPI remote evaluator, return labels and scores, and choose a threshold for your data. The post How to build a remote evaluator in Arize AX with Jev appeared first on Arize AI.

    Arize AI10 min read
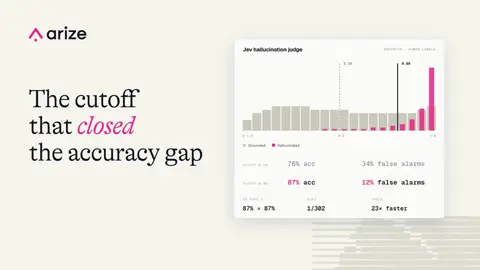
  • Jev vs. LLM-as-a-Judge: Accuracy and cost benchmarks

    We benchmarked Jev against Claude Opus 5 and GPT-5.6 Terra on accuracy, cost, and latency. Learn how threshold tuning changes hallucination detection. The post Jev vs. LLM-as-a-Judge: Accuracy and cost benchmarks appeared first on Arize AI.

    Arize AI10 min read
  • Real-time LLM guardrails with Jev: comparing latency and cost

    Compare Jev and GPT-5.4 nano for real-time LLM guardrails, with demo results on latency, cost, and checks on agent inputs, replies, and tool calls. The post Real-time LLM guardrails with Jev: comparing latency and cost appeared first on Arize AI.

    Arize AI11 min read

Showing 9 of 9 stories

You're all caught up.

AiByts Weekly Brief

Get the top AI news and tools straight to your inbox every week.

Weekly · AI news

Join 15,000+ AI enthusiasts