Introduction to Reinforcement Learning: Multi-Armed Bandit Simulation in Python
When machines learn by themselves The post Introduction to Reinforcement Learning: Multi-Armed Bandit Simulation in Python appeared first on Towards Data Science.
24 stories
When machines learn by themselves The post Introduction to Reinforcement Learning: Multi-Armed Bandit Simulation in Python appeared first on Towards Data Science.
Associate Professor Cathy Wu uses reinforcement learning to help map out improvements to transportation and other multifaceted systems.
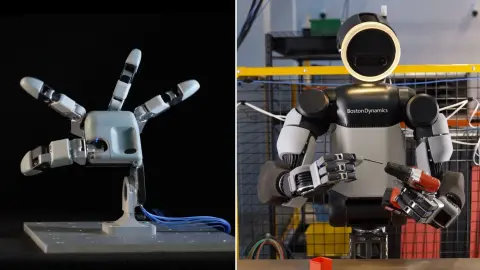
Humanoid robots are increasingly being designed to work in environments built for people, but copying...
The AI system Ataraxos has decisively beaten the best Stratego player of all time. The board game is a tough test for AI because both sides set up their pieces face down. Google Deepmind fell short in 2023 despite a multimillion-dollar budget.
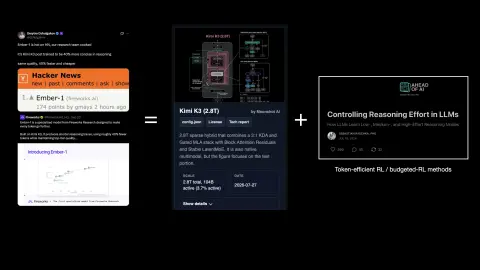
Why I'd invest in post-training existing open-weight LLMs, with Fireworks' Ember-1 as an example of more token-efficient reasoning.
RL environments are where AI models now learn real work: what they are, why labs pay thousands per task, how verifiable rewards work, and what it means for you.
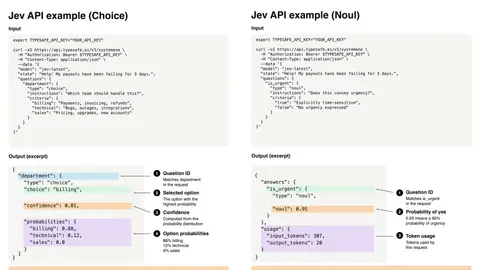
A short note on Jev's generalization, possible encoder-style architecture and training, and Choice and Noul API examples.
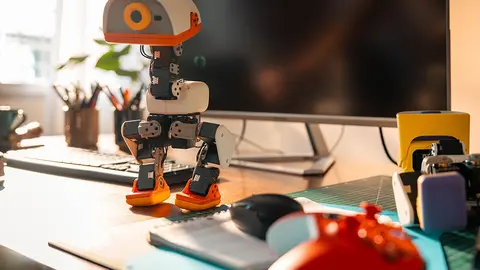
This cute little robot duck isn't actually a toy. It's actually a platform for budding roboticists to train on and develop skills. But heck, this might be the most fun design for a hackable machine we've seen yet.Continue ReadingCategory: Robotics, EngineeringTags: Robot, Artificial Intelligence
Richard Sutton compressed The Bitter Lesson into 26 words. What it means, why he now says LLMs break it, and what it changes for anyone building with AI.
AI agents don't get better by reading more of the internet — they get better by practicing inside simulated worlds built for exactly that purpose. This deep dive explains how modern agents actually learn: why human training data hit a wall, how the reinforcement learning loop works, the…
Short note announcing the release of Build a Reasoning Model From Scratch and linking the publisher and Amazon pages.
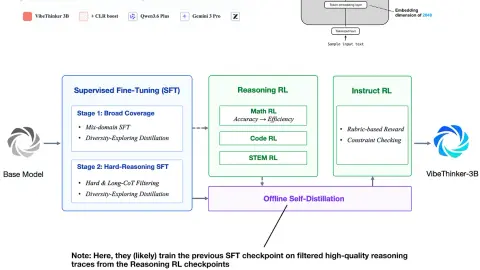
A closer look at VibeThinker-3B, a Qwen2.5-Coder-based model whose reported reasoning gains come from a detailed post-training pipeline.
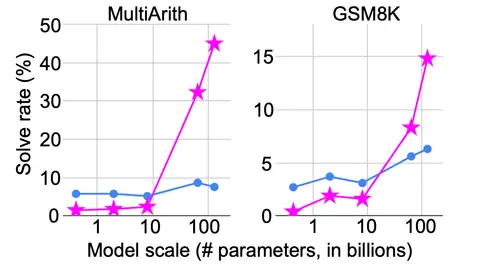
Special thanks to John Schulman for a lot of super valuable feedback and direct edits on this post. Test time compute (Graves et al. 2016, Ling, et al. 2017, Cobbe et al. 2021) and Chain-of-thought (CoT) (Wei et al. 2022, Nye et al.
Reward hacking occurs when a reinforcement learning (RL) agent exploits flaws or ambiguities in the reward function to achieve high rewards, without genuinely learning or completing the intended task.
Is Attention all you need? Mamba, a novel AI model based on State Space Models (SSMs), emerges as a formidable alternative to the widely used Transformer models, addressing their inefficiency in processing long sequences.
Many new Transformer architecture improvements have been proposed since my last post on “The Transformer Family” about three years ago. Here I did a big refactoring and enrichment of that 2020 post — restructure the hierarchy of sections and improve many sections with more recent papers.
[Updated on 2021-02-01: Updated to version 2.0 with several work added and many typos fixed.] [Updated on 2021-05-26: Add P-tuning and Prompt Tuning in the “prompt design” section.] [Updated on 2021-09-19: Add “unlikelihood training”.]
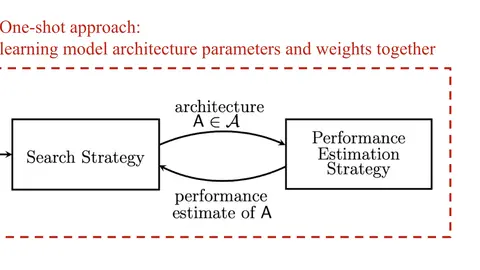
Although most popular and successful model architectures are designed by human experts, it doesn’t mean we have explored the entire network architecture space and settled down with the best option.
Showing 18 of 24 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts